Finding the best GPU hosting for AI model evaluation requires more than comparing accelerator specifications. Reliable model testing depends on consistent hardware, reproducible environments, predictable inference performance, and a clear understanding of total evaluation costs.
Whether you are benchmarking large language models, comparing retrieval-augmented generation pipelines, or validating an AI application before deployment, the right GPU infrastructure can make testing faster and more trustworthy. This guide explains how to evaluate hosting providers for batch testing, reproducibility, and budget control.
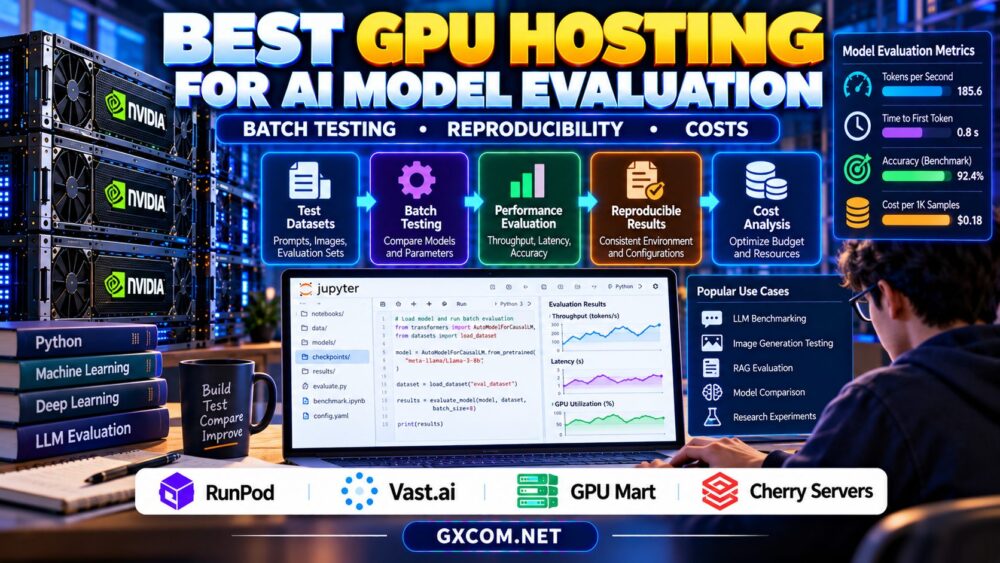
What Makes GPU Hosting Suitable for AI Model Evaluation?
AI model evaluation measures how a model performs against defined datasets, tasks, and quality standards. Unlike ordinary inference hosting, evaluation often requires repeated experiments under controlled conditions.
A suitable GPU environment should provide sufficient VRAM, compatible software, reliable access to test datasets, and stable resource allocation. Teams should also consider deployment time, storage persistence, and whether instances can be recreated consistently.
For capacity planning, our AI inference server sizing guide explains how concurrency, token throughput, and memory affect infrastructure requirements.
Key GPU Evaluation Metrics to Track
Benchmarking should measure both model quality and infrastructure efficiency. Faster hardware does not automatically produce better model answers, and higher throughput may involve compromises in latency or memory consumption.
| Metric | What It Measures | Why It Matters |
|---|---|---|
| Tokens per second | Generation throughput | Inference efficiency |
| Time to first token | Initial response latency | Interactive experience |
| Batch throughput | Completed requests per interval | Evaluation speed |
| Peak VRAM usage | GPU memory consumption | Hardware suitability |
| Cost per evaluation | Total spend divided by completed tests | Budget efficiency |
Record model accuracy, task-specific scores, and error rates separately from hardware measurements. This prevents infrastructure improvements from being confused with changes in model quality.
Batch Testing: Why GPU Throughput Matters
Batch testing processes multiple prompts, images, or evaluation samples together. Batching can improve accelerator utilization, particularly when workloads contain many similar requests.
However, larger batches consume additional memory and may increase individual request latency. The optimal batch size depends on model architecture, sequence lengths, precision, and available VRAM.
Test several batch sizes using the same dataset and configuration. Record completed samples per second, peak memory usage, and failures rather than relying on theoretical accelerator performance.

Our GPU VRAM requirements for LLM inference article explains how quantization, context length, and KV cache affect memory planning.
Reproducibility: The Foundation of Trustworthy Benchmarks
Reproducibility means another evaluation run can be performed under sufficiently similar conditions to support meaningful comparisons. Without consistent environments, differences in software or hardware can distort results.
Record the GPU model, driver version, CUDA or ROCm environment, framework versions, model revision, evaluation dataset, inference settings, and random seeds.
Containers and version-controlled configuration files help recreate environments. Nevertheless, identical seeds do not guarantee bit-for-bit identical results across every GPU architecture or software implementation.
For important comparisons, repeat benchmarks and report variability rather than presenting a single run as definitive.
Best GPU Hosting Providers to Evaluate
The following approved infrastructure providers represent different purchasing approaches. They are comparison candidates, not a verified ranking of current benchmark performance.
RunPod: Flexible AI Evaluation Workflows
RunPod is relevant for teams running model tests, inference experiments, and container-based AI workloads. Evaluate the GPU configurations available for your deployment type, along with storage persistence and instance lifecycle controls.
For repeated experiments, confirm that your environment and datasets can be restored consistently. See our RunPod GPU cloud review for additional provider context.
Vast.ai: Comparing GPU Rental Configurations
Vast.ai provides a marketplace approach to GPU rental. This can help cost-conscious researchers compare different hardware configurations, but individual offers may differ in storage, connectivity, and operating conditions.
When benchmarking across marketplace hosts, document the exact hardware and environment. Avoid treating results from different machines as directly interchangeable without appropriate controls.
GPU Mart: Persistent Evaluation Environments
GPU Mart is worth considering when evaluation projects require longer-lived GPU servers, persistent development environments, or repeated testing over several days.
Compare available accelerator memory, storage options, software access, and billing terms. A persistent environment may reduce setup work, although continuous allocation can increase costs during inactive periods.
Cherry Servers: Dedicated Infrastructure Considerations
Cherry Servers is an approved dedicated infrastructure provider to investigate when evaluating more controlled server deployments. Verify current GPU-enabled product availability, specifications, and provisioning conditions before selecting a configuration.
Dedicated hardware may simplify some consistency requirements, but it does not eliminate software variability or the need for repeatable benchmark procedures.
How to Calculate GPU Model Evaluation Costs
Calculate the cost of completed evaluations, not just the advertised GPU hourly rate. Include compute time, setup, dataset transfers, storage, and failed or repeated experiments.
Suppose a hypothetical GPU costs $0.60 per hour and completes 12,000 evaluation samples in four hours. Compute spending is $2.40, equivalent to $0.20 per 1,000 completed samples.
If setup and retries add another two billable hours, compute spending rises to $3.60. Storage and network charges would increase the total further.
For related workload economics, see our GPU rental cost per AI image guide.
Storage, Dataset Access, and Idle Charges
Large evaluation datasets and multiple model versions can consume significant disk space. Slow dataset loading may leave expensive GPUs underutilized, especially when tests repeatedly access many small files.
Store durable results and important model artifacts separately from disposable compute environments. Check whether persistent volumes continue generating charges after an instance stops.
Our GPU cloud idle costs guide explains common billing risks associated with retained storage and inactive resources.
GPU Hosting Evaluation Checklist
Before purchasing, verify that the GPU supports your model, required precision, and software stack. Run a representative pilot using fixed datasets and documented inference settings.

Measure throughput, latency, memory usage, failure rates, and total spending. Repeat tests under comparable conditions and preserve configuration files, logs, and benchmark outputs.
Finally, compare the cost of completing the entire evaluation campaign, including preparation and reruns.
Compare GPU Hosting for AI Model Evaluation
Choose infrastructure based on repeatable benchmarks, suitable VRAM, batch throughput, and total evaluation costs.
Frequently Asked Questions
Which GPU is best for LLM benchmarking?
The best choice depends on model size, precision, context length, batch size, and evaluation objectives. Benchmark representative workloads before choosing an accelerator.
Can different GPUs produce different evaluation results?
Yes. Numerical precision, software kernels, execution settings, and nondeterministic operations can affect outputs. Document these differences when comparing results.
Is hourly GPU rental cheaper than dedicated hosting?
Hourly rental can suit intermittent experiments, while longer-running projects may benefit from other billing arrangements. Compare total usage and storage costs.
Final Verdict
The best GPU hosting for AI model evaluation combines suitable hardware with reproducible software environments, efficient batch processing, and transparent cost accounting. Compare RunPod, Vast.ai, GPU Mart, and verified Cherry Servers configurations against your actual test workload. Prioritize reliable, repeatable results over headline specifications or unverified performance claims.