

GPU PCIe vs SXM Servers: NVLink, Memory Bandwidth and AI Cluster Costs
Two GPU servers can advertise the same accelerator family yet deliver very different results when a model spans multiple devices. The difference may involve the GPU form factor, interconnect topology, power limits, and the way…
FP8 vs FP4 Inference: GPU Memory Savings, Model Accuracy and Serving Costs
Running large language models is expensive when GPU memory limits batch sizes, model placement, and the number of concurrent requests. Lower-precision inference can reduce those constraints, but choosing a smaller numerical format introduces new questions…
GPU MIG vs Time-Slicing: VRAM Isolation, Multi-Tenant AI and Performance
Sharing one expensive GPU across several AI applications sounds like an obvious way to reduce infrastructure costs. However, giving multiple workloads access to the same accelerator can create unpredictable latency, memory exhaustion, and noisy-neighbor problems.…
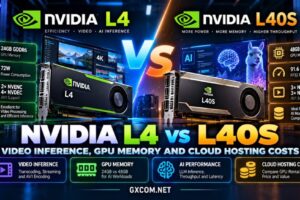
NVIDIA L4 vs L40S: Video Inference, GPU Memory and Cloud Hosting Costs
Choosing between the NVIDIA L4 and L40S is not simply a matter of buying more GPU performance. The right accelerator depends on model size, video processing requirements, inference concurrency, and the actual cost of completing…
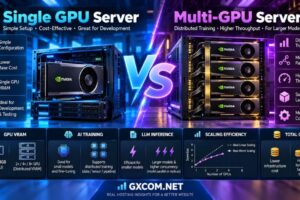
Single GPU vs Multi-GPU Server: AI Training, Inference Scaling and Infrastructure Costs
Adding more GPUs sounds like an obvious way to accelerate artificial intelligence workloads. If one GPU can train or serve a model, four GPUs should be four times faster—or so the assumption goes. Real-world AI…
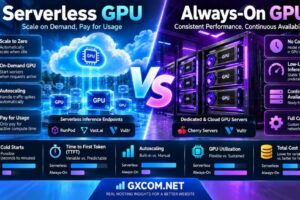
Serverless GPU vs Always-On GPU: Cold Starts, LLM Inference Latency and Cost
Deploying a large language model is no longer just a question of choosing the right GPU. The way that GPU is provisioned, kept available, scaled, and billed can have an equally important impact on application…
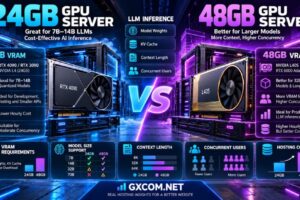
24GB vs 48GB GPU Server: VRAM Requirements, LLM Inference and Hosting Costs
Choosing between a 24GB and 48GB GPU server can determine whether your large language model runs comfortably, struggles with memory limits, or becomes unnecessarily expensive to host. However, the decision is more complicated than comparing…
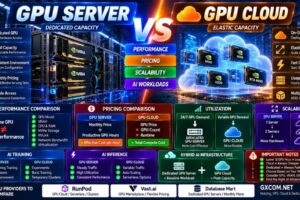
GPU Server vs GPU Cloud: Performance, Pricing and Which Is Better for AI?
AI infrastructure can be deployed in two very different ways: rent a dedicated GPU server for continuous access to the hardware, or use GPU cloud infrastructure that can be provisioned when workloads need it. Both…
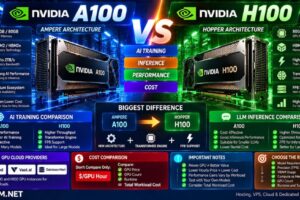
NVIDIA A100 vs H100: AI Training, Inference, Performance and Cost Compared
NVIDIA A100 and H100 are two of the most widely recognized data center GPUs for artificial intelligence, machine learning, large language models, and high-performance computing. But they belong to different generations. The A100 is based…
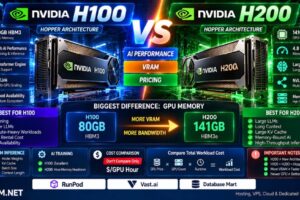
NVIDIA H100 vs H200: AI Performance, VRAM, Pricing and Which GPU Should You Choose?
NVIDIA H100 and H200 are two of the most important data center GPUs for generative AI, large language models, machine learning, and high-performance computing. They are also closely related. Both are based on NVIDIA’s Hopper…
NVIDIA GPU vs AMD GPU Server: Which GPU Hosting Solution Is Better?
Choosing between an NVIDIA GPU vs AMD GPU Server is an important decision for businesses, developers and AI teams building GPU-accelerated applications. Both NVIDIA and AMD provide powerful graphics processors designed for high-performance computing, artificial…
GPU Server vs Cloud GPU: Which AI Infrastructure Should You Choose?
Choosing between a GPU Server vs Cloud GPU is an important decision for businesses, developers and AI teams building modern computing workloads. Both solutions provide access to powerful GPU acceleration, but they differ significantly in…
GPU Server vs CPU Server: Which Server Is Better for Your Workload?
Choosing between a GPU Server vs CPU Server depends on the type of workload you need to run. While CPU servers remain the foundation of traditional computing, GPU servers have become increasingly important for artificial…