Sharing one expensive GPU across several AI applications sounds like an obvious way to reduce infrastructure costs. However, giving multiple workloads access to the same accelerator can create unpredictable latency, memory exhaustion, and noisy-neighbor problems.
In this GPU MIG vs time-slicing comparison, we examine how NVIDIA Multi-Instance GPU differs from CUDA time-slicing, including VRAM isolation, Kubernetes scheduling, multi-tenant inference, hardware compatibility, and cloud hosting costs.
GPU MIG vs Time-Slicing: Quick Verdict
NVIDIA MIG is the stronger choice when supported hardware must serve multiple workloads with defined memory and compute boundaries. It partitions physical GPU resources into independently addressable instances.
GPU time-slicing is useful when several trusted applications need intermittent GPU access and strict performance isolation is unnecessary. Workloads share underlying resources rather than receiving dedicated hardware partitions.
For production AI services, choose based on memory requirements, latency objectives, and workload isolation—not simply the number of containers that can access a GPU.
Our NVIDIA GPU server providers guide offers additional infrastructure options.
What Is NVIDIA Multi-Instance GPU?
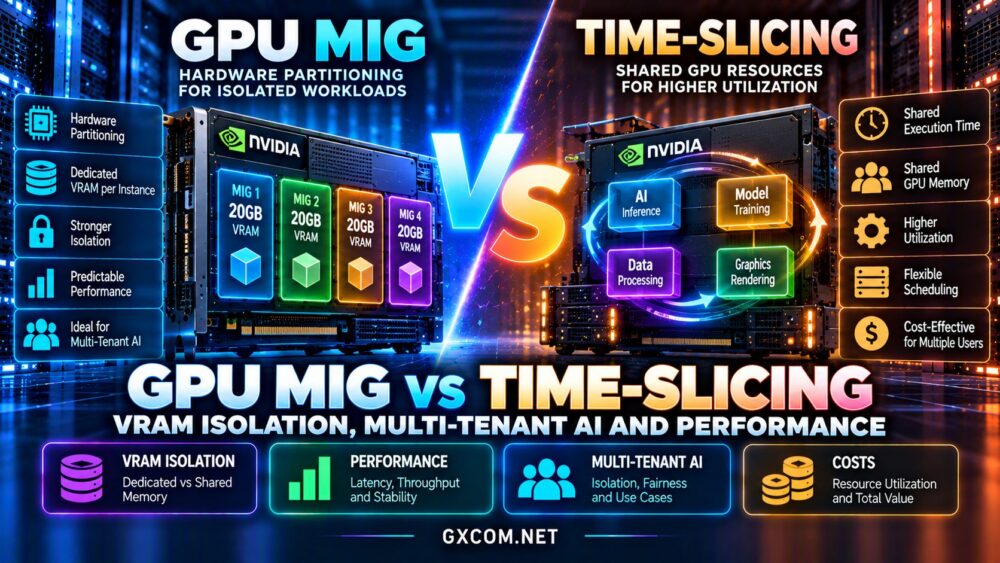
Multi-Instance GPU, or MIG, is an NVIDIA technology that divides supported physical GPUs into smaller hardware-isolated instances.
Each instance receives a defined allocation of GPU compute resources and memory. This helps reduce interference between independent applications running on the same accelerator.
For example, an operator may allocate different MIG profiles to inference services with different memory requirements, provided the GPU supports those configurations.
MIG does not create unlimited partitions. The number, sizes, and supported combinations depend on the exact accelerator model and generation.
Supported families include selected NVIDIA A100, A30, H100, H200, and newer data center GPUs. Compatibility must be checked against NVIDIA’s current MIG support matrix.
What Is GPU Time-Slicing?
GPU time-slicing allows multiple applications to share access to one GPU by interleaving their execution.
In Kubernetes, the NVIDIA device plugin can advertise multiple shared resource replicas backed by the same physical accelerator.
These replicas are scheduling allocations, not separate physical GPUs.
Unlike MIG, ordinary NVIDIA device-plugin time-slicing does not establish independent GPU memory or fault-isolation boundaries between replicas.
Applications compete for available VRAM and compute resources. A memory-intensive process may affect other workloads sharing the device.
Time-slicing is therefore better suited to cooperative, trusted applications with manageable memory demand.
GPU MIG vs Time-Slicing: Technical Comparison
| Feature | NVIDIA MIG | Time-Slicing |
|---|---|---|
| Resource model | Hardware GPU partitions | Shared execution access |
| VRAM allocation | Defined per MIG instance | Shared memory pool |
| Fault isolation | Hardware isolation between instances | Shared fault domain |
| Performance consistency | Stronger resource predictability | Depends on competing workloads |
| Hardware support | Selected MIG-capable GPUs | Broader supported GPU range |
| Kubernetes integration | MIG Manager and device plugin | Device-plugin sharing configuration |
| Best fit | Isolated inference services | Intermittent trusted workloads |
Actual performance still depends on GPU generation, partition profile, driver version, and application behavior.
VRAM Isolation: The Most Important Difference
GPU memory determines whether a model can load, how much KV cache it can maintain, and how many requests it can process concurrently.
With MIG, an application receives the memory capacity associated with its assigned instance. Another MIG tenant cannot simply consume that partition’s allocated VRAM.

This makes capacity planning easier for services requiring predictable model residency.
Memory Risks with Time-Slicing
With ordinary time-slicing, multiple processes access the same physical memory pool. Advertising several GPU replicas does not divide VRAM into guaranteed equal shares.
If combined allocations exceed available memory, applications may encounter CUDA out-of-memory errors.
Administrators must control workload placement, application memory consumption, and concurrency to avoid oversubscription.
Memory verdict: MIG is preferable when enforceable hardware memory boundaries are required. Time-slicing requires greater trust and operational coordination.
Multi-Tenant AI: Isolation and Noisy Neighbors
Multi-tenant AI platforms often serve different customers or applications from shared infrastructure.
One tenant may generate sustained inference traffic while another runs occasional experiments.
Without suitable isolation, competing workloads can affect response times, memory availability, and service reliability.
MIG provides dedicated hardware resource partitions that help establish more predictable performance boundaries.
Time-slicing trades those boundaries for flexible shared access, which can work well when workloads are short, intermittent, and centrally controlled.
However, hardware partitioning is not a complete security architecture. Tenant separation still requires appropriate container, operating system, network, and access controls.
Inference Performance: Throughput vs Latency
The best sharing method depends on whether your priority is total completed requests or consistent response time.
Time-slicing may improve GPU utilization when several applications would otherwise leave the accelerator idle.
But concurrent workloads can compete for execution time, producing variable latency during demand spikes.
MIG can reduce cross-partition interference, although smaller instances have less compute and memory capacity than the full GPU.
LLM Inference and Model Size
Before choosing a MIG profile, calculate memory required for model weights, runtime buffers, and KV cache at the intended context length.
A model that fits on a full GPU may not fit inside a smaller MIG instance.
For larger language models, full-GPU allocation or multi-GPU deployment may be more appropriate.
Our AI GPU VPS providers comparison examines related deployment choices.
Kubernetes GPU Sharing and Scheduling
The NVIDIA GPU Operator and Kubernetes device plugin provide mechanisms for managing MIG resources and shared GPU access.
With MIG, administrators configure supported instance profiles and expose them as schedulable resources.
With time-slicing, the device plugin can advertise multiple replicas of an underlying GPU resource.
Increasing the replica count allows more pods to request shared access, but it does not increase physical GPU capacity.
Monitoring Shared GPU Workloads
Track GPU memory utilization, application latency, throughput, error rates, and resource saturation.
Some per-container GPU monitoring capabilities are limited when using device-plugin time-slicing, so validate observability before deployment.
For production clusters, establish admission policies and workload limits that prevent one service from overwhelming shared infrastructure.
What About CUDA MPS?
CUDA Multi-Process Service, or MPS, is another NVIDIA mechanism for sharing GPU execution resources.
It should not be confused with ordinary time-slicing or MIG.
MPS can coordinate multiple CUDA clients and, in supported configurations, enforce certain memory and compute limits.
Its capabilities, restrictions, and Kubernetes integration differ from hardware MIG partitioning.
Check current NVIDIA documentation before combining sharing technologies or assuming a particular deployment mode is supported.
GPU Hardware Compatibility
Not every NVIDIA accelerator supports MIG.
For example, NVIDIA L4 and L40S GPUs do not provide MIG functionality, despite being capable inference accelerators.
By contrast, supported A100 and H100 configurations can expose MIG profiles.
Even within a supported product family, available profiles and software requirements can differ.
Read our NVIDIA L4 vs L40S comparison to evaluate alternative inference hardware.
GPU MIG vs Time-Slicing Costs
Sharing GPUs can improve utilization, but the cheapest configuration is not necessarily the most economical.
MIG may reduce wasted capacity by assigning appropriately sized partitions to separate workloads.
Time-slicing may be attractive when applications use only a small fraction of GPU time.
However, contention, failed requests, and unpredictable latency can increase the effective cost of operating a service.
Calculate cost per successful inference request, including compute rental, storage, data transfer, and operational overhead.
For broader budgeting, consult our affordable GPU servers guide.
GPU Cloud Providers Worth Comparing
RunPod: GPU Deployment and Inference
RunPod provides GPU cloud infrastructure for AI development and inference workloads.
Evaluate available GPU models, deployment options, and whether your chosen product exposes full-device access or a managed sharing abstraction.
Do not assume that renting an A100 or H100 automatically grants permission to configure MIG.
Vast.ai: Marketplace GPU Capacity
Vast.ai offers marketplace-based GPU rentals with host-dependent configurations.
It can be useful for experiments and flexible capacity planning, but verify isolation, available memory, host policies, and interruption risks.
Vultr: Cloud GPU Infrastructure
Vultr offers cloud infrastructure and GPU products suitable for evaluating dedicated accelerator deployments.
Confirm current GPU inventory and the supported virtualization or sharing model before purchasing.

GPU Mart: GPU VPS and Dedicated Servers
GPU Mart is another option for buyers comparing GPU VPS and dedicated GPU infrastructure.
Check the actual accelerator, administrative privileges, and whether hardware partitioning is supported by the selected service.
For a provider-level purchasing comparison, read our RunPod vs Vast.ai analysis.
How to Benchmark GPU Sharing Fairly
Deploy identical models and inference software, then test full-GPU operation, supported MIG profiles, and time-sliced access separately.
Measure successful requests per second, p95 and p99 latency, VRAM consumption, and failure rates.
Increase concurrent users gradually to identify the point where contention becomes unacceptable.
Repeat measurements under sustained load and include realistic model-loading behavior.
Finally, calculate operating cost per completed request at your required service level.
Frequently Asked Questions
Does GPU time-slicing isolate VRAM?
No. Ordinary NVIDIA device-plugin time-slicing does not provide hardware memory isolation between shared replicas.
Is MIG faster than time-slicing?
Not universally. MIG provides stronger resource isolation, while total throughput depends on workload size, partition profiles, and GPU utilization.
Can NVIDIA L40S use MIG?
No. L40S is not a MIG-capable GPU.
Can MIG and time-slicing be combined?
Yes, certain NVIDIA GPU Operator configurations can apply time-slicing to MIG resources, subject to hardware and software support.
Which option is better for multi-tenant inference?
MIG is generally preferable when predictable memory allocation and stronger resource isolation are required. Time-slicing suits cooperative workloads that tolerate contention.
Final Verdict: MIG or Time-Slicing?
The GPU MIG vs time-slicing decision depends on how much isolation your applications require and how effectively they utilize GPU resources.
Choose MIG for supported hardware serving multiple workloads that need defined VRAM allocations and more predictable performance.
Choose time-slicing when trusted applications have intermittent demand and can tolerate shared memory and execution resources.
Compare RunPod, Vast.ai, Vultr, and GPU Mart according to the actual GPU model and sharing controls available.
Benchmark real inference workloads before committing to an architecture. Better utilization creates value only when reliability and application performance remain acceptable.