Understanding NVIDIA GPU VRAM requirements for LLM inference is essential before renting an AI server. A language model that fits into GPU memory during loading may still fail when users submit longer prompts or multiple requests arrive simultaneously.
Model weights are only one part of the memory budget. Quantization, context length, KV cache, inference framework overhead, and concurrent sequences all influence the GPU capacity required for reliable deployment.
This guide explains practical VRAM calculations, compares memory-saving techniques, and helps you evaluate GPU hosting without paying for unnecessary hardware.
How Much VRAM Does an LLM Need?
Start with model parameter count and numerical precision. A simplified weight-memory estimate multiplies the number of parameters by the bytes stored per parameter.
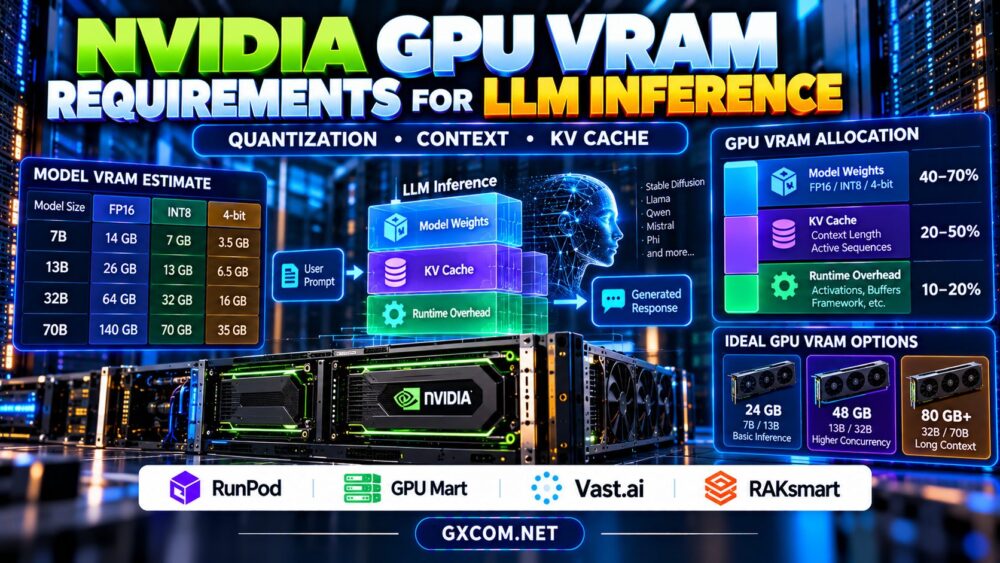
For example, a seven-billion-parameter model requires approximately 14 GB for FP16 weights alone, using decimal units. An eight-bit representation reduces the theoretical weight requirement to approximately 7 GB, while four-bit weights require roughly 3.5 GB.
Actual deployments consume more memory because quantization metadata, runtime buffers, activations, and KV cache require additional capacity.
| Model Size | FP16 Weights | INT8 Theoretical Weights | 4-bit Theoretical Weights |
|---|---|---|---|
| 7B parameters | 14 GB | 7 GB | 3.5 GB |
| 13B parameters | 26 GB | 13 GB | 6.5 GB |
| 32B parameters | 64 GB | 32 GB | 16 GB |
| 70B parameters | 140 GB | 70 GB | 35 GB |
These figures are mathematical estimates, not guaranteed deployment requirements. They exclude additional allocations and assume the stated parameter count represents stored model weights.
FP16, INT8, and 4-bit Quantization Compared
Quantization reduces the memory needed to store model weights by using lower-precision representations. This can make larger models accessible on less expensive NVIDIA GPU configurations.
FP16 is a common reference point for weight storage. INT8 can reduce theoretical weight memory by approximately half, while four-bit quantization can reduce it further.
However, actual memory savings depend on the quantization format, grouping metadata, runtime implementation, and whether some layers remain at higher precision.
Quantization may also affect model quality and inference performance. A smaller model footprint does not guarantee faster token generation because kernels, dequantization overhead, and GPU architecture matter.
Benchmark the exact quantized model before selecting a hosting plan. Our NVIDIA AI GPU servers guide provides broader accelerator selection context.
Why KV Cache Increases GPU Memory Usage
During autoregressive inference, transformers commonly retain key and value tensors from previously processed tokens. This KV cache avoids recomputing the entire attention history for every generated token.

A simplified cache-memory formula for conventional attention is:
KV cache bytes = 2 × layers × KV heads × head dimension × active tokens × bytes per element.
The number of active tokens includes tokens held across running sequences. Models using grouped-query or multi-query attention may have fewer KV heads than query heads, substantially reducing cache requirements.
For illustration, assume 32 layers, eight KV heads, a head dimension of 128, and FP16 cache values. The resulting cache is approximately 128 KiB per token. At 8,192 active tokens, that is about 1 GiB.
This calculation describes one hypothetical architecture. Real allocations depend on model design, cache precision, paging, and inference engine behavior.
Context Length and Concurrent Users
Longer contexts increase the amount of attention history retained during generation. A model supporting a large maximum context does not mean your GPU can serve many users at that context length simultaneously.
For instance, eight active requests with 4,000 cached tokens each represent approximately 32,000 active tokens. The cache budget can therefore become significant even when quantized model weights fit comfortably.
Continuous batching improves GPU utilization by coordinating multiple requests, but it also requires careful memory scheduling.
Set practical context limits and monitor active token counts, cache utilization, and out-of-memory errors. Our AI inference server sizing guide explains how to translate concurrency into throughput requirements.
Choosing Between 24GB, 48GB, and Larger GPUs
A 24GB NVIDIA GPU may suit smaller quantized models, limited concurrency, and development workloads. A 48GB configuration offers more room for larger weights, longer contexts, or additional active sequences.
Higher-memory accelerators become relevant when models exceed single-GPU capacity or production traffic requires substantial cache headroom.
Do not treat these memory tiers as universal model compatibility guarantees. A particular model may fit at startup but exhaust memory during real requests.
Multi-GPU tensor parallelism can distribute model computation and weights, although communication overhead and interconnect topology affect performance.
For deployment architecture decisions, compare GPU VPS versus dedicated GPU servers before choosing virtualized or exclusive hardware.
Four Approved GPU Hosting Providers to Evaluate
RunPod: Flexible LLM Deployment
RunPod is relevant for teams testing GPU-based inference workloads. Compare available accelerator memory, deployment options, storage persistence, and product-specific billing.
Its suitability depends on whether you need experimental environments, persistent workers, or customer-facing inference capacity.
GPU Mart: Persistent GPU Infrastructure
GPU Mart is worth evaluating when persistent GPU server configurations match your model requirements. Confirm available VRAM, GPU exclusivity, driver access, and administrative control.
For continuous inference, compare the full monthly cost against flexible rental alternatives.
Vast.ai: Marketplace GPU Capacity
Vast.ai provides another route for comparing GPU rental offers. Examine individual listings for actual accelerator specifications, host reliability, storage, and networking.
Production deployments should include recovery planning rather than relying exclusively on an attractive hourly rate.
RAKsmart: Dedicated Infrastructure Evaluation
RAKsmart may be considered for dedicated infrastructure procurement. Verify current GPU product availability, memory configuration, provisioning terms, and support before including any offer in a purchasing shortlist.
For an additional provider-focused reference, see our RunPod GPU cloud review.
Calculate the Real Cost of LLM VRAM
Compare effective cost per completed inference request, not merely price per gigabyte of VRAM. A higher-memory GPU may improve concurrency but still deliver poor value when utilization remains low.
Include model loading time, persistent storage, bandwidth, idle capacity, and engineering overhead. Measure tokens per second and p95 latency under realistic workloads.
Our affordable GPU servers comparison provides additional budget-oriented purchasing context.
Practical VRAM Sizing Checklist
Identify the exact model and quantization format. Calculate approximate weight memory, estimate KV cache at peak active tokens, and reserve space for runtime overhead.

Load the model, benchmark representative context lengths, and increase concurrency until latency or memory limits become unacceptable. Repeat tests after changing inference engines or quantization formats.
Choose a configuration with sufficient headroom for traffic spikes and operational recovery rather than buying the smallest GPU that can load the model once.
Compare NVIDIA GPU Hosting for LLM Inference
Evaluate VRAM capacity, quantization support, context limits, and real inference throughput before choosing a server.
Frequently Asked Questions
Can a 24GB GPU run a 70B LLM?
Not normally with all conventional FP16 or four-bit weights resident on one 24GB GPU. Offloading or distributed configurations may be possible, with performance tradeoffs.
Does four-bit quantization reduce KV cache memory?
Not automatically. Weight quantization and KV cache precision are separate settings. Some inference engines support additional cache compression.
Why does inference run out of VRAM after loading?
Growing KV cache, concurrent requests, runtime allocations, and longer contexts can exceed the remaining memory budget.
Final Verdict
NVIDIA GPU VRAM requirements for LLM inference depend on model weights, quantization, KV cache, context length, and concurrency. Estimate memory mathematically, then validate the complete workload through testing. Compare RunPod, GPU Mart, Vast.ai, and verified RAKsmart configurations against measured performance and total hosting costs before purchasing.