

AMD GPU Servers for LLM Inference: ROCm Compatibility, Memory and Hosting Costs
AMD GPU servers for LLM inference are increasingly relevant to teams evaluating alternatives to NVIDIA-based AI infrastructure. AMD Instinct accelerators can offer substantial memory capacity and computing resources, but selecting hardware is only part of…
NVIDIA GPU Servers for TensorRT-LLM: Throughput, Batching and Hosting Costs
Choosing NVIDIA GPU servers for TensorRT-LLM requires more than comparing GPU memory and hourly rental prices. Large language model inference depends on throughput, request concurrency, batching efficiency, memory management, and latency targets. A powerful accelerator…
NVIDIA GPU VRAM Requirements for LLM Inference: Quantization, Context and KV Cache
Understanding NVIDIA GPU VRAM requirements for LLM inference is essential before renting an AI server. A language model that fits into GPU memory during loading may still fail when users submit longer prompts or multiple…
AI Inference Server Sizing: Concurrent Users, Tokens per Second and GPU Memory
AI inference server sizing starts with the experience your users expect, not the GPU model you want to rent. A chatbot handling occasional questions needs a different configuration from an API serving hundreds of simultaneous…
AMD Instinct MI300X GPU Server Review: HBM, ROCm and LLM Deployment Costs
Deploying large language models requires a careful balance between GPU memory, inference throughput, software compatibility, and infrastructure costs. A powerful accelerator can reduce hardware requirements, but only when its capabilities match the application. The AMD…
NVIDIA L4 vs L40S: Video Inference, GPU Memory and Cloud Hosting Costs
Choosing between the NVIDIA L4 and L40S is not simply a matter of buying more GPU performance. The right accelerator depends on model size, video processing requirements, inference concurrency, and the actual cost of completing…
NVIDIA H200 GPU Server Review: HBM Memory, LLM Inference and Hosting Cost
Large language models have changed how businesses evaluate GPU servers. Raw compute performance remains important, but GPU memory capacity, memory bandwidth, interconnects, and infrastructure costs increasingly determine whether a deployment is practical. This NVIDIA H200…
NVIDIA RTX PRO 6000 Blackwell Server Review: 96GB VRAM and AI Workloads
Running large AI models is no longer only about raw computing power. GPU memory capacity, inference throughput, software compatibility, and long-term operating costs increasingly determine whether a deployment succeeds. This NVIDIA RTX PRO 6000 Blackwell…
Single GPU vs Multi-GPU Server: AI Training, Inference Scaling and Infrastructure Costs
Adding more GPUs sounds like an obvious way to accelerate artificial intelligence workloads. If one GPU can train or serve a model, four GPUs should be four times faster—or so the assumption goes. Real-world AI…
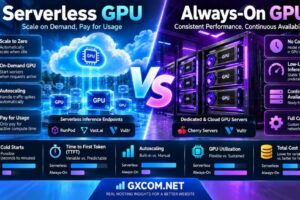
Serverless GPU vs Always-On GPU: Cold Starts, LLM Inference Latency and Cost
Deploying a large language model is no longer just a question of choosing the right GPU. The way that GPU is provisioned, kept available, scaled, and billed can have an equally important impact on application…
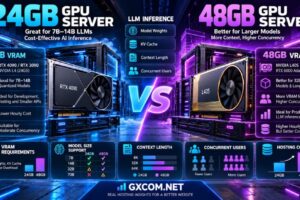
24GB vs 48GB GPU Server: VRAM Requirements, LLM Inference and Hosting Costs
Choosing between a 24GB and 48GB GPU server can determine whether your large language model runs comfortably, struggles with memory limits, or becomes unnecessarily expensive to host. However, the decision is more complicated than comparing…
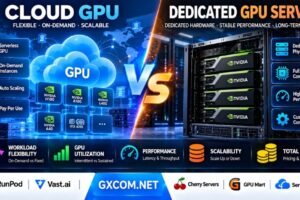
Cloud GPU vs Dedicated GPU Server: AI Workload Flexibility, Utilization and Total Cost
Should you rent GPUs from a cloud platform or choose a dedicated GPU server for artificial intelligence? The answer depends on more than GPU specifications or advertised hourly prices. AI workloads have very different resource…
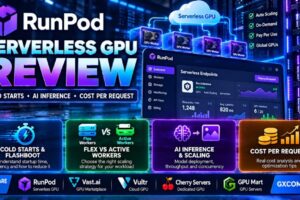
RunPod Serverless GPU Review: Cold Starts, AI Inference and Cost per Request
This RunPod Serverless GPU review examines how RunPod handles AI inference, cold starts, autoscaling, GPU worker utilization, and cost per request. For developers building LLM APIs, image generation services, AI agents, or production inference pipelines,…
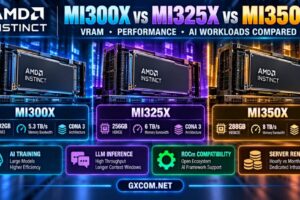
AMD Instinct MI300X vs MI325X vs MI350X Servers: VRAM, Performance and AI Workloads
Choosing between the AMD Instinct MI300X, MI325X, and MI350X can significantly affect the cost, performance, and scalability of an AI server deployment. These data center accelerators are designed for demanding workloads such as large language…
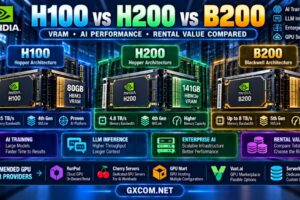
NVIDIA H100 vs H200 vs B200 Servers: VRAM, AI Performance and Rental Value Compared
Choosing between NVIDIA H100, H200, and B200 GPU servers is an important infrastructure decision for organizations running large language models, AI training pipelines, and high-throughput inference services. Although all three accelerators target demanding data center…