

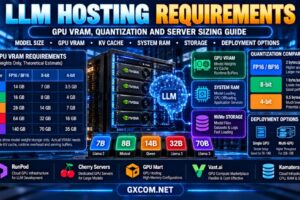
LLM Hosting Requirements: GPU VRAM, Quantization and Server Sizing Guide
Understanding LLM hosting requirements is essential before deploying a large language model on a GPU server, cloud instance, or private infrastructure. Choosing too little GPU memory can prevent a model from loading, while renting unnecessarily…
AI Inference Server Hosting: GPU Memory, Latency and Cost Compared
Choosing the right AI inference server hosting solution is essential for developers and businesses deploying large language models, AI chatbots, retrieval-augmented generation (RAG) applications, and production AI APIs. Unlike AI training, inference focuses on running…
NVIDIA A100 vs H100: AI Training, Inference, Performance and Cost Compared
NVIDIA A100 and H100 are two of the most widely recognized data center GPUs for artificial intelligence, machine learning, large language models, and high-performance computing. But they belong to different generations. The A100 is based…
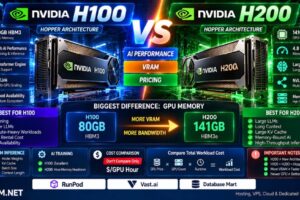
NVIDIA H100 vs H200: AI Performance, VRAM, Pricing and Which GPU Should You Choose?
NVIDIA H100 and H200 are two of the most important data center GPUs for generative AI, large language models, machine learning, and high-performance computing. They are also closely related. Both are based on NVIDIA’s Hopper…