

RunPod vs Vast.ai: GPU Rental Reliability, Deployment Flexibility and AI Costs
Renting a GPU is no longer simply about finding the lowest hourly rate. For AI developers, unreliable instances, storage charges, slow deployments, and interrupted training jobs can make an apparently inexpensive GPU surprisingly costly. In…
Serverless GPU vs Always-On GPU: Cold Starts, LLM Inference Latency and Cost
Deploying a large language model is no longer just a question of choosing the right GPU. The way that GPU is provisioned, kept available, scaled, and billed can have an equally important impact on application…
24GB vs 48GB GPU Server: VRAM Requirements, LLM Inference and Hosting Costs
Choosing between a 24GB and 48GB GPU server can determine whether your large language model runs comfortably, struggles with memory limits, or becomes unnecessarily expensive to host. However, the decision is more complicated than comparing…
Serverless GPU Platforms Review: Cold Starts, Autoscaling and Production AI Costs
This serverless GPU platforms review compares the technologies, deployment models, and operating costs behind modern AI inference infrastructure. We examine GPU cold starts, autoscaling behavior, concurrency, latency, utilization, and the cost of serving real production…
Vast.ai GPU Marketplace Review: Host Reliability, GPU Selection and Hidden Costs
This Vast.ai GPU marketplace review examines host reliability, GPU selection, instance interruptions, storage and networking considerations, and the hidden costs that can affect AI training and inference workloads. Vast.ai offers access to GPU computing through…
RunPod Serverless GPU Review: Cold Starts, AI Inference and Cost per Request
This RunPod Serverless GPU review examines how RunPod handles AI inference, cold starts, autoscaling, GPU worker utilization, and cost per request. For developers building LLM APIs, image generation services, AI agents, or production inference pipelines,…
Multi-GPU Server Deals: Affordable 4-GPU and 8-GPU Hosting Options
Multi-GPU server deals can help AI developers, research teams, and businesses access the computing power of four or eight GPUs without purchasing and maintaining expensive physical hardware. However, an affordable 4-GPU or 8-GPU server is…
RTX 4090 GPU Server Deals: Affordable 24GB GPU Hosting Offers
RTX 4090 GPU server deals can be an attractive option for developers, AI researchers, creators, and small businesses that need powerful GPU computing without paying for a high-memory enterprise accelerator. With 24GB of GDDR6X memory,…
NVIDIA H200 GPU Rental Deals: High-Memory AI Servers Compared
H200 GPU rental deals are worth comparing when AI workloads require large GPU memory, high memory bandwidth, and the ability to process demanding models without constantly moving data between GPU and system memory. However, renting…
Best GPU Servers for AI Startups: Cloud vs Dedicated Infrastructure Compared
Finding the best GPU servers for AI startups is about more than choosing a powerful NVIDIA or AMD accelerator. Early-stage AI companies must balance model performance, GPU memory, infrastructure costs, deployment speed, and the ability…
Best GPU Server Deals: GPU Cloud and Dedicated GPU Offers Compared
GPU servers have become essential infrastructure for AI training, LLM inference, machine learning, generative AI, rendering, scientific computing, and other highly parallel workloads. But finding the best GPU server deals requires more than comparing the…
Best Black Friday GPU Server Deals: GPU Cloud and Dedicated GPU Discounts
Black Friday can be one of the best times to compare GPU server pricing, but the largest advertised discount does not always deliver the lowest AI compute cost. GPU hosting providers use very different pricing…
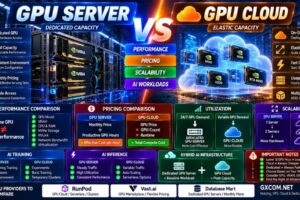
GPU Server vs GPU Cloud: Performance, Pricing and Which Is Better for AI?
AI infrastructure can be deployed in two very different ways: rent a dedicated GPU server for continuous access to the hardware, or use GPU cloud infrastructure that can be provisioned when workloads need it. Both…
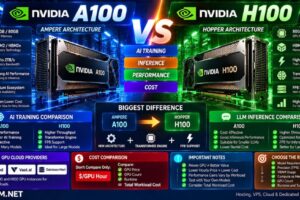
NVIDIA A100 vs H100: AI Training, Inference, Performance and Cost Compared
NVIDIA A100 and H100 are two of the most widely recognized data center GPUs for artificial intelligence, machine learning, large language models, and high-performance computing. But they belong to different generations. The A100 is based…
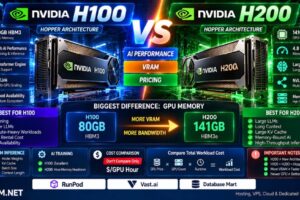
NVIDIA H100 vs H200: AI Performance, VRAM, Pricing and Which GPU Should You Choose?
NVIDIA H100 and H200 are two of the most important data center GPUs for generative AI, large language models, machine learning, and high-performance computing. They are also closely related. Both are based on NVIDIA’s Hopper…