The NVIDIA H100 has become one of the most recognizable GPUs in artificial intelligence infrastructure. Designed around NVIDIA's Hopper architecture, H100 servers are built for demanding workloads including large language models, generative AI, machine learning, AI inference, and high-performance computing.
However, choosing NVIDIA H100 Server Hosting involves much more than finding a provider with an H100 logo on its pricing page. Buyers need to compare H100 variants, GPU memory, server architecture, networking, billing models, availability, and total computing cost.
This guide explains NVIDIA H100 performance, pricing factors, server configurations, and hosting providers to help you determine whether H100 infrastructure is right for your AI workload.
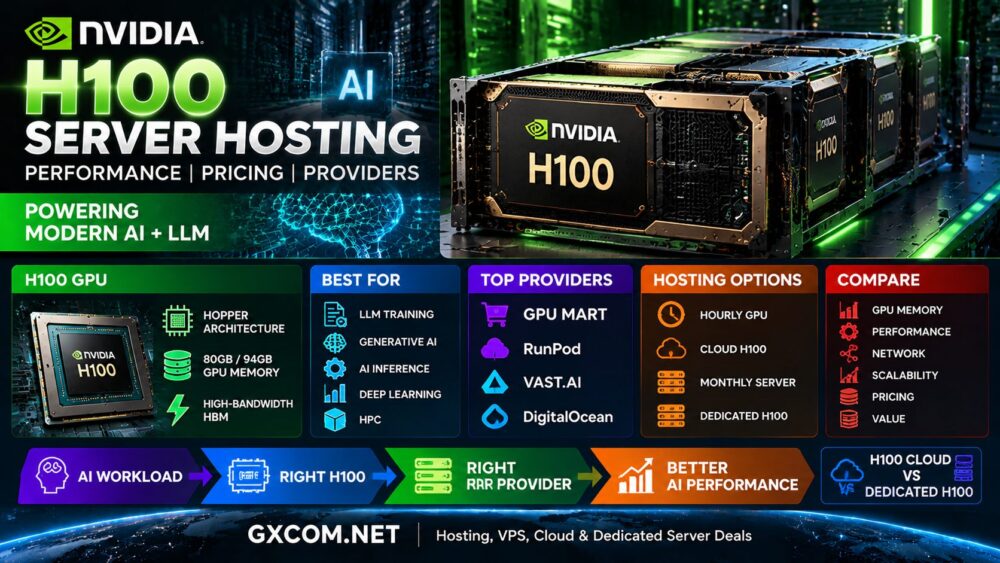
NVIDIA H100 Server Hosting at a Glance
| Feature | H100 SXM | H100 NVL |
|---|---|---|
| Architecture | Hopper | Hopper |
| GPU Memory | 80GB | 94GB |
| Memory Type | HBM3 | HBM3 |
| Memory Bandwidth | 3.35TB/s | 3.9TB/s |
| Form Factor | SXM | PCIe |
| Primary Use | Large-scale AI and HPC | AI and LLM workloads |
What Is an NVIDIA H100 Server?
An NVIDIA H100 server is a GPU-accelerated server equipped with one or more H100 data center GPUs.
Unlike consumer graphics cards, the H100 was designed specifically for data center computing and artificial intelligence. It includes fourth-generation Tensor Cores and NVIDIA's Transformer Engine, technologies aimed at accelerating modern AI workloads.
Common H100 applications include:
- Large language model training
- Generative AI
- AI inference
- Deep learning
- Natural language processing
- Scientific computing
- High-performance computing
For a broader look at NVIDIA's GPU portfolio, see our
Best NVIDIA GPU Servers
guide.
NVIDIA H100 Performance
H100 performance depends heavily on the specific workload and server configuration.
The H100 SXM provides 80GB of GPU memory and 3.35TB/s of memory bandwidth, while H100 NVL provides 94GB and 3.9TB/s. Multi-GPU H100 systems can also use high-speed NVIDIA NVLink connectivity.
These capabilities make H100 infrastructure particularly relevant for workloads where compute throughput and GPU memory bandwidth are critical.
However, real-world AI performance also depends on:
- Model architecture
- Model size
- Training or inference
- Numerical precision
- Batch size
- Software optimization
- Number of GPUs
- Storage performance
- Network architecture
H100 for Large Language Models
Large language models are one of the most important applications for H100 server hosting.
LLMs require substantial GPU memory and computational resources for both training and inference. Larger models may need multiple GPUs working together, making interconnect performance and server architecture increasingly important.
H100 infrastructure can be used for:
- LLM training
- Fine-tuning
- Retrieval-augmented generation
- Enterprise AI assistants
- LLM inference
- AI APIs
H100 for Generative AI
Generative AI workloads extend beyond text models. H100 servers can support multimodal AI, image generation, speech applications, coding assistants, enterprise AI platforms, and other GPU-intensive applications.
For production environments, organizations should consider not only model performance but also inference throughput, latency, utilization, and cost per request.
H100 SXM vs H100 NVL
| Factor | H100 SXM | H100 NVL |
|---|---|---|
| GPU Memory | 80GB | 94GB |
| Memory Bandwidth | 3.35TB/s | 3.9TB/s |
| Form Factor | SXM | PCIe |
| Multi-GPU Focus | Strong | Flexible server deployments |
| Best Fit | High-performance AI clusters | AI and large-model deployments |
Do not assume that every provider advertising “H100 hosting” offers exactly the same H100 configuration. Always check the GPU variant and complete server specifications before purchasing.
H100 vs A100 vs L40S
H100 is not automatically the best choice for every AI project.
A100 remains relevant for established machine-learning workloads, while L40S can provide an attractive combination of AI inference and graphics acceleration. Smaller projects may also achieve better cost efficiency with less expensive GPUs.
Our
H100 vs A100 vs L40S
comparison explains these differences in more detail.
Best NVIDIA H100 Server Hosting Providers
H100 infrastructure is available through specialized GPU hosting companies, GPU marketplaces, and larger cloud platforms. Each model has different advantages.
GPU Mart
GPU Mart focuses specifically on GPU hosting and offers H100-oriented infrastructure alongside other NVIDIA GPU server options.
Its hosting model is particularly relevant to users looking for dedicated GPU infrastructure rather than only short-lived cloud instances.
When evaluating GPU Mart or another dedicated provider, compare the exact H100 model, CPU, RAM, NVMe storage, network port, traffic allowance, deployment time, and contract period.
RunPod
RunPod is popular among AI developers who want flexible access to GPU computing without purchasing physical hardware.
Its cloud-oriented approach can be attractive for AI development, model testing, inference, and workloads where usage changes over time.
Vast.ai
Vast.ai uses a marketplace model that allows users to compare GPU resources offered by different hosts.
This can produce attractive pricing for cost-sensitive workloads, but buyers should look beyond the GPU model and compare reliability, storage, networking, host characteristics, and availability.
DigitalOcean
DigitalOcean offers H100 GPU infrastructure within its broader cloud ecosystem.
This approach can appeal to development teams that want GPU computing alongside virtual machines, networking, storage, databases, and other cloud services.
H100 Hosting Provider Comparison
| Provider | Hosting Style | Best For |
|---|---|---|
| GPU Mart | GPU-focused hosting | Dedicated GPU workloads |
| RunPod | GPU cloud | AI development and flexible workloads |
| Vast.ai | GPU marketplace | Price-sensitive GPU computing |
| DigitalOcean | Cloud GPU infrastructure | Cloud application development |
How Much Does H100 Server Hosting Cost?
There is no single H100 hosting price.
The final cost can vary substantially depending on:
- H100 variant
- Number of GPUs
- Dedicated or shared infrastructure
- CPU resources
- System RAM
- NVMe storage
- Bandwidth
- Data center location
- Hourly or monthly billing
- Reserved capacity
This is why comparing only the advertised GPU hourly rate can be misleading.
Hourly H100 Rental vs Monthly H100 Server
| Billing Model | Best For | Main Advantage |
|---|---|---|
| Hourly H100 Rental | Testing and temporary workloads | Flexible usage |
| On-Demand Cloud | Variable AI workloads | Fast scaling |
| Monthly H100 Server | Continuous workloads | Predictable budgeting |
| Dedicated Multi-GPU | Large AI projects | Dedicated resources |
For temporary development or benchmarking, hourly rental can reduce upfront commitment. Continuous high-utilization workloads may justify comparing monthly or dedicated server pricing.
See our
GPU Server Rental
guide for a broader explanation of rental models.
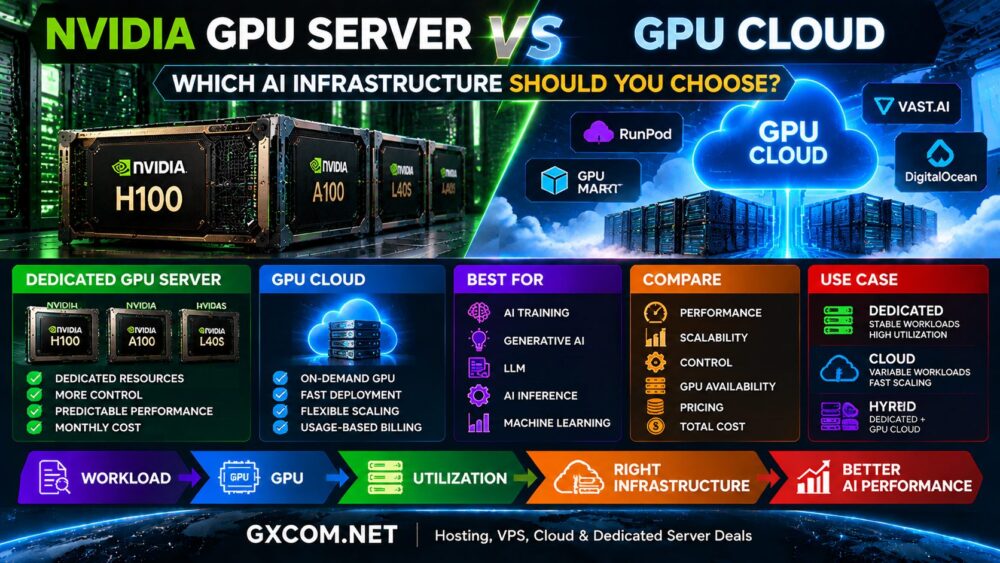
H100 Cloud vs Dedicated H100 Server
Cloud H100 instances emphasize flexibility. Dedicated H100 servers emphasize predictable access to hardware.
| Feature | Cloud H100 | Dedicated H100 |
|---|---|---|
| Deployment | Fast | Provider dependent |
| Scaling | Flexible | Hardware dependent |
| Hardware Access | Service dependent | Dedicated |
| Billing | Usually usage based | Often monthly |
| Ideal Workload | Variable | Continuous |
Is H100 Still Worth It?
Newer GPU generations do not automatically make H100 infrastructure irrelevant.
H100 remains a capable data center accelerator with broad software support and substantial deployment across AI infrastructure. The more useful question is whether its performance, availability, and current provider pricing make sense for a particular workload.
For some projects, newer hardware may provide advantages. For others, H100 availability or pricing can make it an attractive option. Smaller inference and development workloads may not require an H100 at all.
H100 vs AMD MI300X
AMD Instinct MI300X provides another high-end option for organizations evaluating large-model infrastructure.
One important difference is the software ecosystem: NVIDIA uses CUDA, while AMD's Instinct platform uses ROCm. MI300X also emphasizes very large GPU memory capacity.
Organizations considering both ecosystems should compare actual model performance, software compatibility, GPU memory requirements, provider availability, and total cost rather than relying on vendor specifications alone.
See our
AMD Instinct MI300X Server
guide for more information.
How to Choose an H100 Hosting Provider
Before renting an H100 server, compare the complete infrastructure rather than only the GPU name.
Check:
- Exact H100 model and memory
- Dedicated vs virtualized GPU
- Number of GPUs
- CPU configuration
- System RAM
- NVMe storage
- Network speed
- Data transfer charges
- Data center location
- Billing minimums
- Technical support
- Upgrade path
Common H100 Hosting Mistakes
Choosing H100 Only Because It Is Powerful
An expensive accelerator can be poor value if the workload cannot utilize its performance.
Ignoring the H100 Variant
H100 configurations differ. Check GPU memory, form factor, server architecture, and interconnects rather than assuming every H100 server is identical.
Ignoring Storage and Networking
A powerful GPU can still be constrained by slow data loading, insufficient storage performance, or weak networking.
Comparing Only Hourly Price
Total project cost depends on how efficiently the workload runs, along with storage, bandwidth, CPU, RAM, and idle time.
NVIDIA H100 Server Hosting Checklist
- Define the AI workload.
- Calculate GPU memory requirements.
- Choose H100 configuration.
- Determine the required number of GPUs.
- Compare cloud and dedicated hosting.
- Check storage and network performance.
- Estimate total workload cost.
- Compare providers and availability.
Final Thoughts
NVIDIA H100 server hosting remains a powerful option for large language models, generative AI, machine learning, inference, and high-performance computing.
H100 SXM and H100 NVL target demanding workloads with high-bandwidth memory and NVIDIA's established CUDA ecosystem, but the most powerful configuration is not automatically the most cost-effective choice.
GPU Mart, RunPod, Vast.ai, and DigitalOcean represent different approaches to accessing GPU infrastructure, ranging from dedicated hosting and GPU marketplaces to flexible cloud deployments.
The right H100 provider depends on your workload, required GPU memory, deployment duration, scalability, networking, and budget. Compare total computing value rather than simply choosing the lowest advertised hourly price.