

GPU Server Rental for Blender Rendering: VRAM and Cost per Frame
Choosing the right GPU server rental for Blender rendering can reduce production delays and improve the economics of animation, architectural visualization, and 3D product design. However, the cheapest GPU rental is not necessarily the most…
NVIDIA L40S GPU Server Review: 48GB VRAM, Rendering and AI Inference Costs
Choosing a GPU server for AI inference or professional rendering requires more than comparing theoretical processing power. Memory capacity, workload compatibility, deployment costs, and sustained utilization determine whether an accelerator delivers practical value. The NVIDIA…
NVIDIA L4 vs L40S: Video Inference, GPU Memory and Cloud Hosting Costs
Choosing between the NVIDIA L4 and L40S is not simply a matter of buying more GPU performance. The right accelerator depends on model size, video processing requirements, inference concurrency, and the actual cost of completing…
OVHcloud GPU Server Review: Dedicated Accelerators, VRAM and Workload Fit
Renting a GPU server is no longer just about finding the fastest NVIDIA accelerator. For AI inference, machine learning, video processing, and graphics workloads, the right decision depends on GPU memory, deployment flexibility, CPU resources,…
Vultr Cloud GPU Review: NVIDIA Instances, Storage and AI Deployment Costs
Renting an NVIDIA GPU in the cloud can eliminate the upfront expense of buying specialized hardware. However, choosing a GPU instance involves more than comparing accelerator models or advertised hourly rates. GPU memory, storage persistence,…
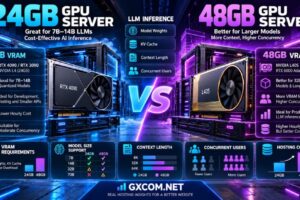
24GB vs 48GB GPU Server: VRAM Requirements, LLM Inference and Hosting Costs
Choosing between a 24GB and 48GB GPU server can determine whether your large language model runs comfortably, struggles with memory limits, or becomes unnecessarily expensive to host. However, the decision is more complicated than comparing…
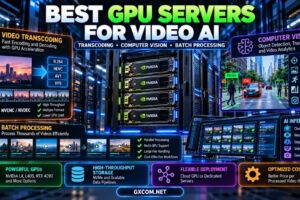
Best GPU Servers for Video AI: Transcoding, Computer Vision and Batch Processing
Best GPU servers for video AI are not necessarily the servers with the most expensive graphics cards or the highest advertised AI compute performance. Video transcoding, computer vision, real-time analytics, and batch processing place different…
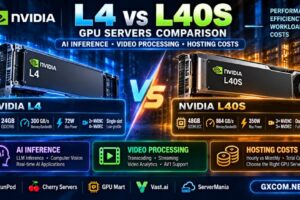
NVIDIA L4 vs L40S GPU Servers: AI Inference, Video Processing and Hosting Costs
NVIDIA L4 vs L40S is an important comparison for businesses choosing GPU servers for AI inference, video processing, computer vision, and generative AI. Both accelerators use NVIDIA’s Ada Lovelace architecture, but they differ significantly in…
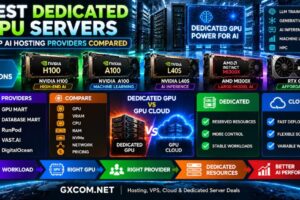
Best Dedicated GPU Servers: Top AI Hosting Providers Compared
Artificial intelligence workloads are becoming more demanding as organizations train larger models, deploy generative AI applications, run high-volume inference, and process increasingly complex datasets. Cloud GPUs provide excellent flexibility, but workloads that run continuously can…
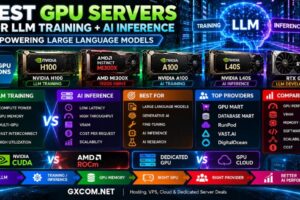
Best GPU Servers for LLM Training and AI Inference
Large language models have changed the way organizations think about GPU infrastructure. Training, fine-tuning, and serving modern AI models can require enormous amounts of compute power, GPU memory, memory bandwidth, storage performance, and network capacity.…