Deploying large language models requires a careful balance between GPU memory, inference throughput, software compatibility, and infrastructure costs. A powerful accelerator can reduce hardware requirements, but only when its capabilities match the application.
The AMD Instinct MI300X GPU server is designed for demanding AI and high-performance computing workloads. With 192GB of HBM3 memory and AMD’s CDNA 3 architecture, it offers substantial capacity for large models and memory-intensive inference.
However, hardware specifications alone cannot determine whether MI300X is more economical than NVIDIA alternatives. ROCm compatibility, deployment complexity, and actual GPU utilization also influence the final cost.
This review examines MI300X hardware, LLM deployment considerations, and the economics of renting AMD GPU infrastructure.
AMD Instinct MI300X Specifications
AMD introduced the MI300X as a data-center accelerator for generative AI, model training, inference, and scientific computing.
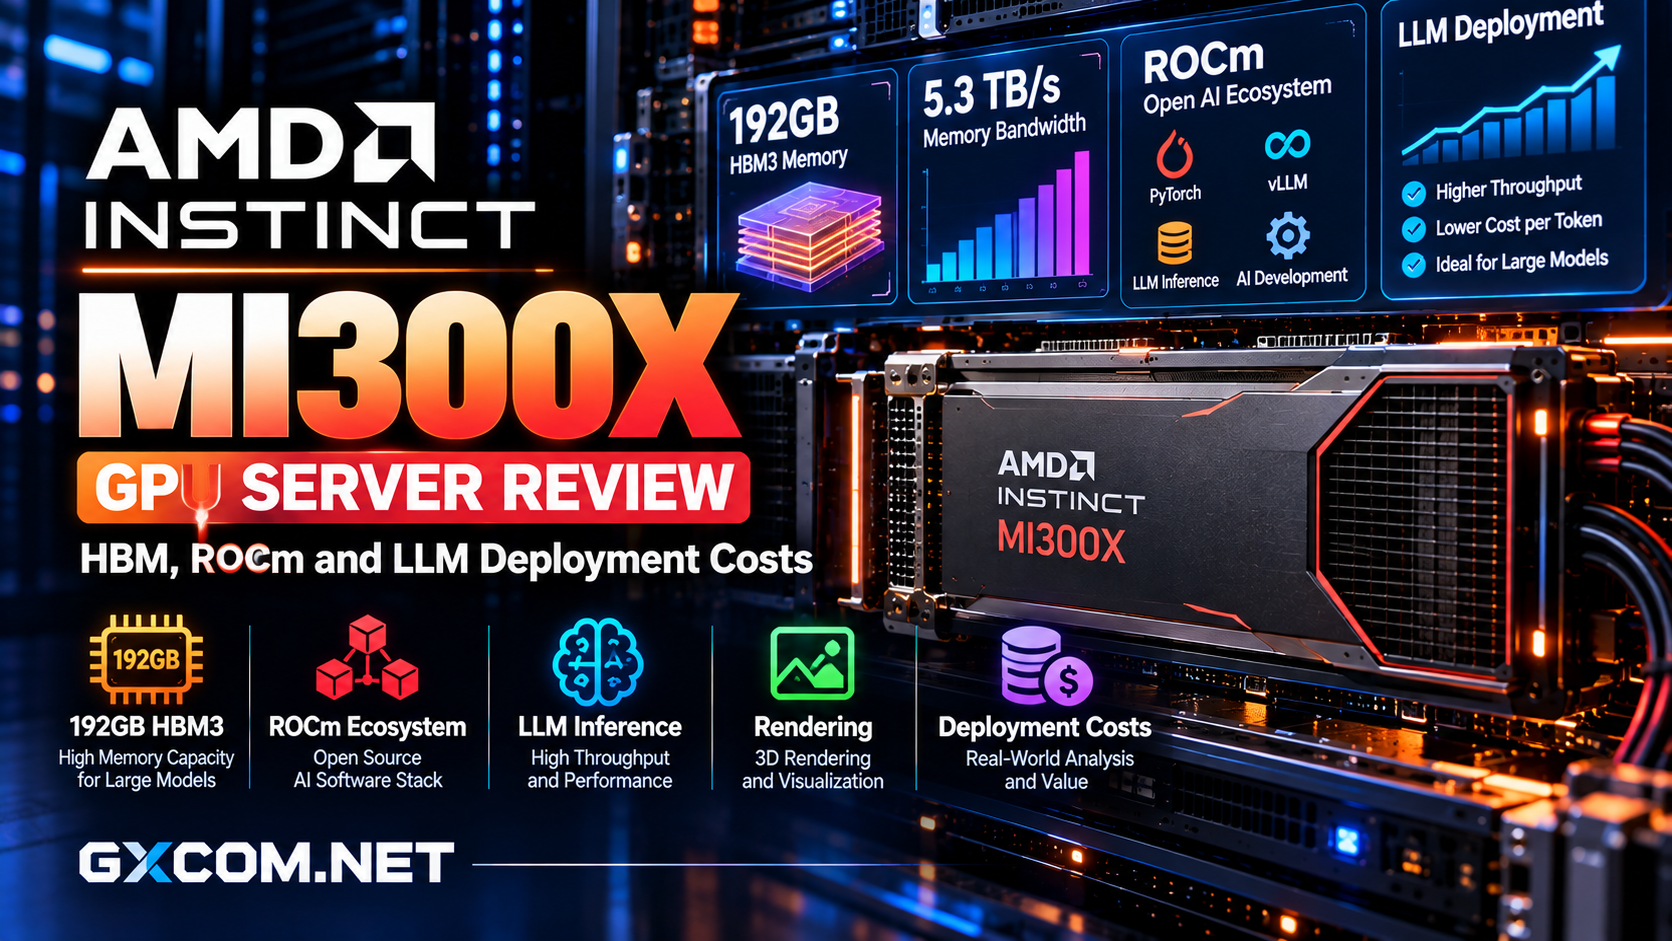
Its specifications include 192GB HBM3 memory, up to 5.3TB/s theoretical memory bandwidth, 304 compute units, and 19,456 stream processors.
The accelerator supports FP8, BF16, and FP16 computation, while its peak board power reaches 750W.
| Specification | AMD Instinct MI300X |
|---|---|
| Architecture | AMD CDNA 3 |
| GPU Memory | 192GB HBM3 |
| Memory Bandwidth | Up to 5.3TB/s |
| Compute Units | 304 |
| Stream Processors | 19,456 |
| Interconnect | AMD Infinity Fabric |
| Peak Board Power | 750W |
These are manufacturer specifications, not measured application benchmarks. Server configuration and software optimization affect delivered performance.
Why 192GB HBM3 Matters for LLMs
Large language models consume GPU memory for model weights, activations, runtime buffers, and key-value caches.
The MI300X’s 192GB capacity can reduce the need to distribute certain inference workloads across multiple accelerators.
For illustration, a 70-billion-parameter model stored at two bytes per parameter requires approximately 140GB for weights alone. Runtime overhead and cache requirements increase total consumption.
Quantization can reduce memory requirements, but the resulting throughput and model quality depend on implementation.
Memory Bandwidth and Token Generation
LLM inference frequently involves moving substantial amounts of data between GPU memory and compute units.
MI300X’s theoretical 5.3TB/s bandwidth is particularly relevant to memory-bound operations. Nevertheless, higher bandwidth does not guarantee proportionally faster token generation.

Batch size, attention implementation, model architecture, and inference software determine practical results.
Our NVIDIA GPU server providers guide provides additional hardware comparisons.
ROCm: The Software Compatibility Question
AMD’s ROCm platform provides GPU computing tools, libraries, and framework integration for supported Instinct accelerators.
ROCm supports important machine learning workflows using PyTorch and compatible inference frameworks.
However, applications developed specifically around NVIDIA CUDA may require changes before running efficiently on AMD hardware.
Custom CUDA extensions, specialized kernels, and third-party dependencies deserve particular attention.
Deploying vLLM on MI300X
AMD provides documentation for running vLLM with ROCm-enabled environments. Container-based deployment can simplify dependency management and improve reproducibility.
A typical workflow involves selecting a supported Linux environment, installing the appropriate GPU driver, using compatible ROCm containers, loading model weights, and validating inference requests.
Before production deployment, confirm compatibility between ROCm, PyTorch, vLLM, model architecture, and quantization formats.
Do not assume that an optimization available on CUDA has an identical ROCm implementation.
Multi-GPU Servers and Infinity Fabric
AMD’s MI300X platform integrates eight accelerators with a combined 1.5TB of HBM3 memory.
Infinity Fabric provides high-speed GPU connectivity for supported multi-accelerator operations.
This architecture can support large model deployments requiring tensor parallelism or distributed processing.
However, eight GPUs do not automatically provide eight times the performance. Communication overhead, model partitioning, and network topology influence scaling efficiency.
For multi-node deployments, verify the server interconnect and distributed framework configuration before committing to a large cluster.
MI300X vs NVIDIA H100
The MI300X offers more memory capacity per accelerator than the standard 80GB H100 configuration.
This difference can simplify selected large-model inference deployments where GPU memory is the primary constraint.
The H100 benefits from NVIDIA’s established CUDA ecosystem and specialized NVLink-based multi-GPU infrastructure.
Choosing between them requires testing the same model, numerical precision, batch size, and latency target.
Software maturity and engineering effort may outweigh hardware specifications for teams with substantial CUDA dependencies.
MI300X GPU Rental Economics
The most meaningful comparison is cost per completed workload rather than the hourly GPU rental rate.
For LLM inference, useful measurements include generated tokens per second, request latency, GPU utilization, and cost per million output tokens.
Cost per Million Tokens = Total Billable Cost / Output Tokens Generated × 1,000,000
Suppose a hypothetical GPU deployment costs $2 per hour and produces 500,000 output tokens during that hour.
The compute cost would be $4 per million output tokens, excluding storage, networking, and operational expenses.
This example is illustrative, not a measured MI300X benchmark or current provider quotation.
Hidden Deployment Costs
ROCm migration, model optimization, idle GPU time, persistent storage, and engineering support can affect total expenses.
Long-running inference services should benchmark sustained workloads rather than relying on short performance tests.
Our affordable GPU servers comparison examines related infrastructure purchasing decisions.
MI300X Hosting Providers and Alternatives
Vultr: AMD Instinct Cloud GPU
Vultr officially offers MI300X GPU cloud infrastructure and ROCm-based deployment resources.
It is a relevant choice for teams evaluating AMD acceleration without purchasing physical servers. Confirm regional availability, instance configuration, and current billing conditions.
RunPod: Alternative GPU Cloud Workflows
RunPod provides GPU cloud infrastructure for model development and inference.

Compare available accelerator models, container workflows, and persistent storage options against your MI300X requirements.
Cherry Servers: Dedicated Infrastructure
Cherry Servers offers dedicated server infrastructure for sustained computing workloads.
Evaluate its available GPU configurations and management requirements when considering bare metal alternatives.
GPU Mart: Dedicated GPU Hosting
GPU Mart provides dedicated GPU server options for organizations prioritizing longer-running workloads.
Confirm available accelerators and software compatibility before comparing its offerings with MI300X deployments.
Explore our AI GPU VPS providers comparison and bare metal server providers guide for additional options.
Who Should Choose AMD MI300X?
MI300X is particularly attractive for memory-intensive LLM inference, large-model experimentation, and organizations prepared to operate ROCm-based software.
It may be less suitable when an application depends heavily on unsupported CUDA-specific components or when smaller GPUs already satisfy throughput requirements.
Before renting, benchmark the actual model, verify software compatibility, and estimate complete deployment costs.
Final Verdict
The AMD Instinct MI300X GPU server combines substantial HBM3 capacity with high memory bandwidth and an increasingly capable ROCm software ecosystem.
Its strongest opportunity lies in large-model workloads where memory capacity reduces deployment complexity.
However, the best purchasing decision depends on validated inference throughput, software compatibility, operational overhead, and total cost per completed workload.