

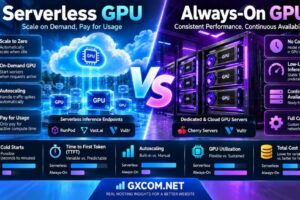
Serverless GPU vs Always-On GPU: Cold Starts, LLM Inference Latency and Cost
Deploying a large language model is no longer just a question of choosing the right GPU. The way that GPU is provisioned, kept available, scaled, and billed can have an equally important impact on application…