What Makes Cloud Servers Highly Available?
High availability cloud servers are designed to keep applications accessible when individual infrastructure components fail. Instead of relying on one virtual machine, a high-availability architecture uses redundant resources, health checks, and a defined recovery process. The goal is to reduce service interruption, not promise that failures will never occur.
A single cloud instance can still become unavailable because of operating-system problems, storage failures, network issues, or deployment mistakes. Businesses should evaluate the entire application path, including databases and DNS, rather than treating a provider’s uptime percentage as proof of end-to-end resilience.
High Availability vs Disaster Recovery
High availability focuses on maintaining service during localized failures. Disaster recovery focuses on restoring operations after more serious incidents, including data corruption, regional disruption, or accidental deletion. Both matter, but they solve different problems.
Define a recovery time objective (RTO), the maximum acceptable restoration period, and a recovery point objective (RPO), the amount of recent data the business can afford to lose. These targets determine whether simple backups, standby servers, or continuous replication are justified.
Our cloud VPS snapshots vs backups guide explains why recovery copies need independent retention and restore testing.
Failover: Active-Passive vs Active-Active
Active-Passive Failover
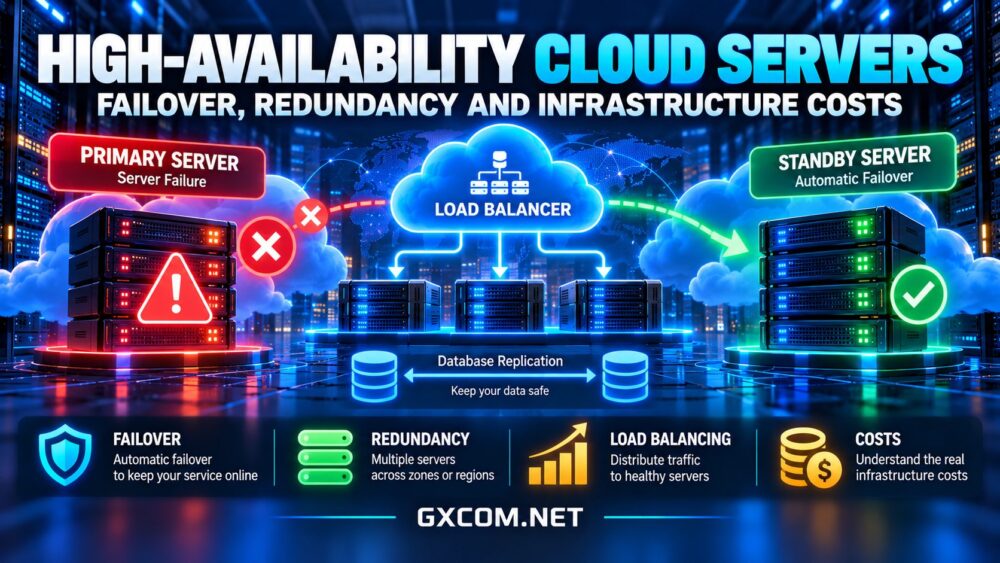
An active-passive design uses a primary server and a standby system. When monitoring detects a qualifying failure, traffic or service ownership moves to the standby. This can simplify application consistency, although the standby still requires capacity, maintenance, and periodic testing.
Failover is rarely instantaneous. Detection intervals, application startup, database promotion, and connection recovery all influence the real interruption experienced by customers.
Active-Active Redundancy
An active-active design runs multiple application instances simultaneously, commonly behind a load balancer. Healthy instances continue serving requests when another fails. This approach can also distribute routine traffic, but applications must manage sessions, shared state, and concurrent database operations correctly.
Active-active application servers do not eliminate a single database failure point. Redundant database architecture and tested promotion procedures may be necessary to meet strict recovery objectives.
Load Balancers and Failure Domains
A load balancer sends traffic to healthy application instances and can stop routing requests to failed nodes. However, the load balancer itself must be resilient. Verify whether the provider’s service has built-in redundancy and how health checks behave during partial outages.
Place redundant resources across distinct failure domains where supported. Separate physical hosts may protect against a hardware fault; separate availability zones may reduce exposure to a localized facility issue. Multiple regions can address broader disruptions, but introduce replication complexity, latency, and transfer expenses.

Automatic scaling serves a different purpose: adjusting capacity as demand changes. Read our cloud server auto scaling guide to compare scaling triggers with failover mechanisms.
Five Cloud Providers to Evaluate
Providers offer different combinations of virtual machines, networking, backups, and managed services. Confirm product-specific features and regional availability before designing an architecture around them.
Vultr: Developer-Managed Redundancy
Vultr is a candidate for teams building redundant application tiers with cloud compute and networking services. Compare available load balancing options, instance placement, storage behavior, and backup policies. Multi-instance deployment still requires application-level configuration.
Kamatera: Configurable Cloud Infrastructure
Kamatera offers configurable cloud server resources that can support custom redundancy plans. Buyers should confirm networking options, backup arrangements, automation capabilities, and the cost of maintaining standby capacity.
Hostwinds: VPS and Cloud Server Redundancy
Hostwinds offers VPS and cloud hosting services that can support applications requiring multiple virtual server instances. Businesses may use separate servers for primary and standby workloads or configure redundant application environments according to their infrastructure requirements.
High availability should not be assumed to be included automatically. Buyers need to verify available networking features, load balancing options, backup services, and server placement. Where automatic failover is required, the application architecture and supporting infrastructure must be configured and tested appropriately.
ScalaHosting: Managed and Self-Managed VPS Options
ScalaHosting provides managed and self-managed VPS hosting options for businesses seeking different levels of server administration. Its services may be relevant to websites and applications that require dependable hosting operations, backups, and an appropriate recovery strategy.
However, managed VPS hosting does not automatically provide multi-node high availability. Businesses should confirm whether their selected plan supports the required redundancy architecture, how backups are handled, and which recovery procedures remain their responsibility. More demanding applications may need additional infrastructure beyond a standard VPS configuration.
Cloudways: Managed Application Hosting
Cloudways may suit compatible web applications whose owners prefer managed server operations. Check whether the selected plan supports the required failover architecture, what support covers, and which recovery tasks remain the customer’s responsibility. Our managed cloud hosting comparison provides additional purchasing context.
What Does High Availability Actually Cost?
Redundancy usually increases baseline spending. A second application server, standby database, load balancer, monitoring service, replicated storage, and additional backups may each create recurring charges. Cross-zone or cross-region traffic can add costs even when customer demand remains unchanged.
Consider a hypothetical single-server deployment costing $40 monthly. Adding a second $40 server and a $15 load balancing service raises the simplified infrastructure total to $95. That excludes database redundancy, backup storage, transfer, engineering time, and support. These figures illustrate budgeting, not current provider quotations.
A standby server may be cheaper than a fully active duplicate under some designs, but it still needs testing and adequate capacity to handle production traffic. Conversely, an active-active configuration may deliver both resilience and usable capacity, potentially improving resource efficiency during normal operation.
Review our cloud VPS bandwidth costs guide before budgeting replication traffic. For purchasing comparisons, consult cloud hosting deals while checking the full architecture cost rather than introductory server prices.
Choose the Right Availability Level
Not every application needs the same redundancy budget. A low-traffic informational website may tolerate a documented restoration window, while a subscription platform processing customer transactions may require redundant application nodes and faster database recovery. Prioritize the business processes that create the greatest financial or reputational exposure during an outage.

Ask providers for written service-level terms and clarify what happens when a dependency fails outside their infrastructure. Service credits generally do not reimburse lost sales, engineering time, or damaged customer relationships. Monitor availability from outside the hosting environment so internal monitoring failures do not conceal an outage.
How to Test a Failover Plan
- Identify dependencies: Map application servers, databases, storage, DNS, and third-party services.
- Set recovery targets: Agree on RTO and RPO before selecting infrastructure.
- Simulate failure: Remove an instance from service and measure detection and recovery.
- Verify data consistency: Check transactions, replication lag, and database promotion.
- Test restoration: Recover from backups independently of the primary environment.
- Review costs: Measure standby resources, network transfer, monitoring, and operational labor.
Final Verdict
High availability is an architectural outcome, not a checkbox on a cloud server plan. Businesses should invest in redundancy according to the cost of downtime and the recovery targets their applications require. Start by removing the most consequential single points of failure, rehearse failover regularly, and compare providers using complete infrastructure and operational costs. A simpler design with tested recovery may be more valuable than an elaborate system nobody knows how to restore.