

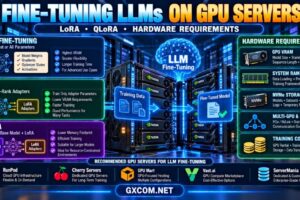
Fine-Tuning LLMs on GPU Servers: LoRA, QLoRA and Hardware Requirements
Choosing the right GPU infrastructure for large language model fine-tuning requires a different approach from ordinary LLM inference. Training workloads must account for model weights, gradients, optimizer states, activations, sequence length, and batch size. As…