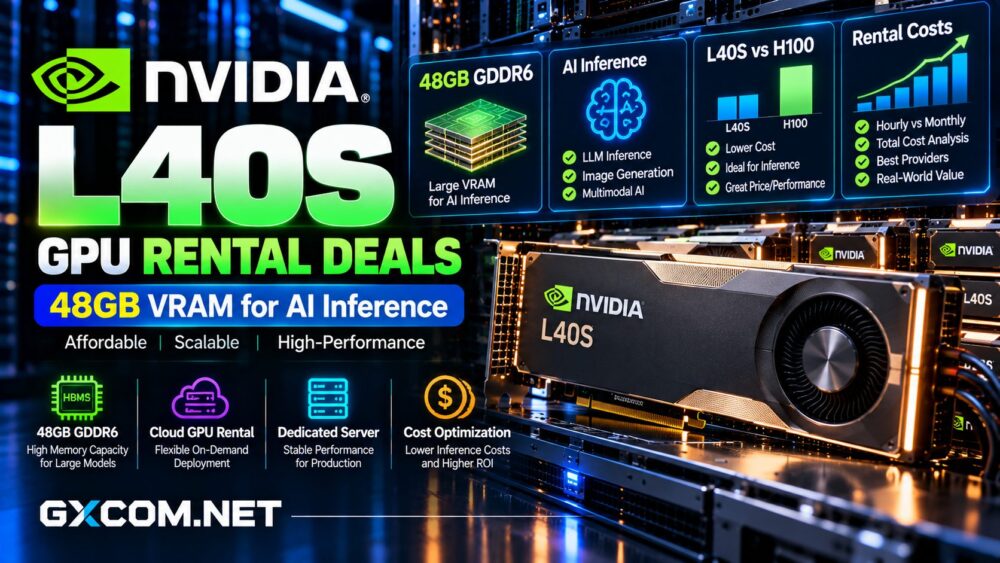
Renting an NVIDIA L40S GPU can be a practical way to deploy AI inference without paying for the memory capacity and training-oriented infrastructure of an H100. With 48GB of GDDR6 ECC memory, the L40S targets workloads that need more room than typical 24GB GPUs but do not necessarily require 80GB-class accelerators.
However, the best NVIDIA L40S GPU rental deals depend on more than the advertised hourly price. Model size, request concurrency, deployment flexibility, storage charges, and sustained utilization all affect the final bill.
本指南对以下内容进行了比较 RunPod, Vultr, GPU Mart, ,以及 Cherry 服务器, explains L40S inference economics, and shows when renting an L40S makes financial sense.
Why Rent an NVIDIA L40S for AI Inference?
The NVIDIA L40S uses Ada Lovelace architecture with fourth-generation Tensor Cores, FP8 acceleration, and 48GB GDDR6 ECC memory. Its published memory bandwidth is 864GB/s, with a maximum power consumption of 350W.
These specifications make it relevant for language-model serving, image generation, multimodal applications, and professional visualization.
| 规格 | NVIDIA L40S |
|---|---|
| 建筑 | 艾达·洛夫莱斯 |
| GPU 内存 | 48GB GDDR6 ECC |
| 内存带宽 | 864GB/s |
| 最大功率 | 350W |
| NVLink | 不支持 |
| Primary Applications | Inference, rendering, generative AI |
Unlike H100-class accelerators, the L40S does not support NVLink. Buyers planning tightly coupled distributed workloads should account for this limitation rather than assuming multiple cards behave like one large GPU.
Best NVIDIA L40S GPU Rental Providers
RunPod: Flexible L40S GPU Cloud
RunPod explicitly lists L40S instances in its GPU catalog. Its Pods provide configurable GPU environments, while Serverless supports inference endpoints that scale according to demand.
Pods are attractive for development, sustained inference, and direct environment control. Serverless can suit applications with unpredictable request volumes, although worker startup behavior and billing differ.
Compare Community Cloud and Secure Cloud availability, storage, CPU allocation, and deployment regions before choosing.
For more background, read our RunPod GPU 云服务评测.
Vultr: L40S Cloud and Enterprise Infrastructure
Vultr publishes an NVIDIA L40S cloud GPU offering covering GPU passthrough, bare-metal configurations, and cluster deployments.
This makes Vultr relevant to businesses combining inference services with broader cloud infrastructure requirements.

Request the exact instance configuration and verify regional capacity, networking, storage, and deployment terms. Enterprise-oriented configurations may not be directly comparable with a single low-cost GPU Pod.
GPU Mart: Dedicated GPU Hosting Alternative
GPU Mart specializes in GPU server infrastructure and is worth evaluating when continuous workloads make dedicated hardware attractive.
For L40S-specific purchasing, confirm the available accelerator model before requesting a quotation. Do not assume that every advertised GPU server includes an L40S.
Compare monthly commitment, CPU resources, system RAM, storage, bandwidth, and support rather than GPU specifications alone.
Cherry Servers: Custom Bare Metal Options
Cherry 服务器 offers configurable GPU-enabled bare-metal infrastructure for AI workloads.
It is an alternative for buyers prioritizing hardware isolation and server-level control. L40S availability should be verified directly before comparing quotations.
Ask whether provisioning, network capacity, and operating system access match your production requirements.
L40S GPU Rental Pricing: Hourly vs Monthly
Hourly rental suits testing, development, and inference services with uncertain demand. Monthly infrastructure becomes more interesting when the same GPU remains busy throughout the billing period.
Use this basic formula:
Monthly Compute Cost = GPU Hourly Rate × Billable Hours
For illustration, an L40S rented at a hypothetical $1 per hour would generate $200 in compute charges over 200 billable hours, or $720 over 720 hours.
These figures are examples, not current supplier quotations. Actual costs depend on the selected service and additional charges.
For broader purchasing options, explore our affordable GPU server comparison.
Is 48GB VRAM Enough for LLM Inference?
For many inference workloads, 48GB offers useful headroom beyond 24GB accelerators. However, model weights are only part of total memory consumption.
KV cache, context length, concurrent requests, framework overhead, and runtime buffers also consume VRAM.
Quantization can reduce model weight requirements, but actual memory usage and output quality depend on the model and implementation.
A model that fits during a single-request test may still exceed available memory under production concurrency.
Benchmark the intended model, precision, context length, and batch size before reserving infrastructure.
L40S vs H100: Which Rental Offers Better Value?
The L40S and H100 address overlapping but different infrastructure requirements.
| 因子 | L40S | H100 SXM |
|---|---|---|
| GPU 内存 | 48GB GDDR6 | 80GB HBM3 |
| 内存带宽 | 864GB/s | 约3.35TB/s |
| NVLink | 不 | 是的 |
| 购买优先级 | Right-sized inference | Demanding training and inference |
The H100 provides substantially greater memory bandwidth and stronger capabilities for demanding workloads, but its rental cost may be higher.
An L40S can deliver better value when a model fits comfortably and meets throughput targets. The H100 may justify its premium when faster processing or additional memory reduces total operating costs.
Compare available configurations in our NVIDIA H100 GPU 租赁优惠 指南。.
Calculate Cost per Million Inference Tokens
Hourly GPU price is not the most useful production metric. Instead, measure the cost of completed inference under realistic traffic.
Cost per Million Output Tokens = Total Infrastructure Cost ÷ Output Tokens × 1,000,000
For example, suppose an inference deployment costs $12 and produces 1.5 million output tokens during the measurement period.
The resulting cost is $8 per million output tokens, excluding any additional expenses not included in the $12.
Measure time to first token, output throughput, p95 latency, GPU utilization, and memory usage alongside this calculation.

Higher throughput is only valuable when latency and output quality remain acceptable.
Pods, Serverless, or Dedicated L40S Hosting?
Choose a GPU Pod when you need environment control, persistent processes, and predictable deployment behavior.
Serverless inference may reduce idle compute expenditure when traffic is intermittent, although cold starts and worker policies require evaluation.
Dedicated servers can suit continuously busy applications that need predictable hardware access and longer-term cost planning.
For alternative GPU deployment models, see our AI GPU VPS 服务商指南.
Hidden Costs and Rental Checklist
Before purchasing, examine persistent storage, data transfer, reserved capacity, idle billing, and termination policies.
Confirm the actual L40S allocation, GPU exclusivity, CUDA compatibility, and whether the advertised price includes sufficient CPU and RAM.
Production teams should also verify backup procedures, regional latency, service support, and recovery options.
A lower hourly rate offers little advantage if insufficient resources or repeated interruptions increase total deployment time.
Final Verdict: Which L40S Rental Deal Should You Choose?
RunPod is a strong starting point for flexible L40S Pods and serverless inference. Vultr offers another clearly documented L40S cloud option, including enterprise-oriented deployment models.
GPU Mart and Cherry Servers deserve consideration for dedicated GPU infrastructure, subject to confirmation of the requested accelerator configuration.
最好的 NVIDIA L40S GPU rental deal is the one that meets memory, latency, throughput, and reliability requirements at the lowest sustainable total cost.
Benchmark your real workload before committing to long-term GPU capacity.