Large language models have changed the way organizations think about GPU infrastructure. Training, fine-tuning, and serving modern AI models can require enormous amounts of compute power, GPU memory, memory bandwidth, storage performance, and network capacity.
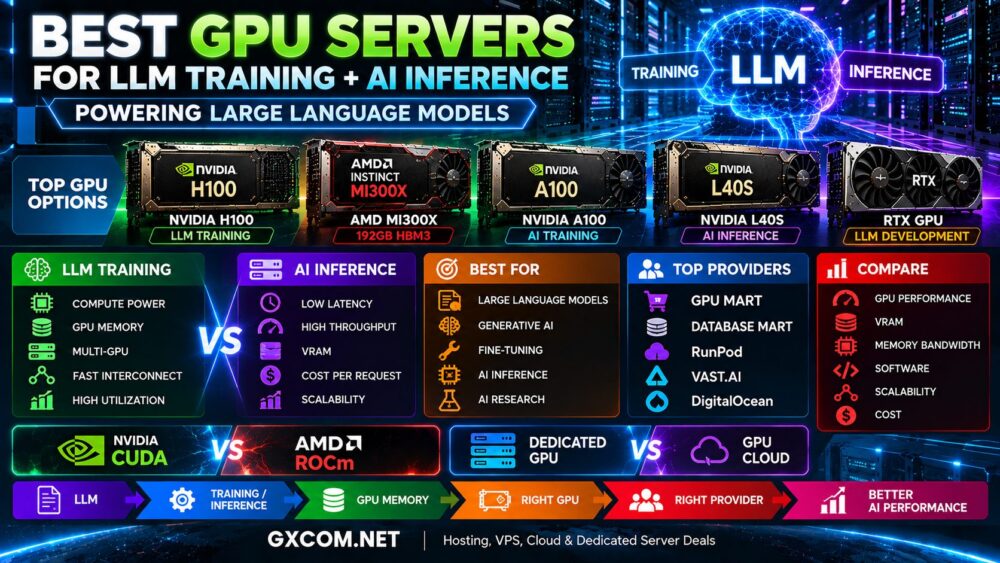
选择 最适合大型语言模型(LLM)训练和人工智能推理的GPU服务器 therefore involves much more than selecting the fastest accelerator. NVIDIA H100, A100, L40S, AMD Instinct MI300X, and lower-cost GPU options can all make sense depending on the model, workload, software ecosystem, and budget.
This guide compares leading GPU server options for LLM training and inference, explains the differences between training and serving models, and explores dedicated GPU servers versus flexible GPU cloud infrastructure.
Best GPUs for LLMs at a Glance
| GPU | 最适合 | 核心优势 | Software |
|---|---|---|---|
| NVIDIA H100 | Large-Scale LLM Training | 高端人工智能加速 | CUDA |
| AMD Instinct MI300X | Memory-Intensive LLMs | 192GB HBM3 | ROCm |
| NVIDIA A100 | Training and Fine-Tuning | 成熟的人工智能生态系统 | CUDA |
| NVIDIA L40S | AI推理 | AI 与图形处理的多功能性 | CUDA |
| RTX级显卡 | Development and Smaller Models | 较低的入门成本 | CUDA |
Why LLMs Need GPU Servers
Large language models rely heavily on parallel mathematical operations. GPUs are designed to perform large numbers of calculations simultaneously, making them much better suited than general-purpose CPUs for many modern AI workloads.
A complete LLM server must balance several resources:
- GPU 计算性能
- GPU内存或VRAM
- 内存带宽
- CPU性能
- 系统内存
- NVMe 存储
- 多GPU通信
- 网络带宽
A powerful GPU can still perform poorly if storage, networking, system memory, or software configuration creates a bottleneck.
LLM Training vs AI Inference
Training and inference have different infrastructure requirements, which is why the best GPU for one workload may not be the best GPU for another.
LLM 训练
Training involves processing enormous datasets and repeatedly updating model parameters. Large-scale training can keep multiple GPUs operating at high utilization for long periods.
Training infrastructure typically prioritizes:
- 计算性能
- 大容量 GPU 内存
- 内存带宽
- 多GPU扩展
- Fast interconnects
- 高速存储
AI推理
Inference happens after a model has been trained. The server processes user requests and generates outputs from the existing model.
Inference infrastructure often prioritizes:
- 延迟
- 吞吐量
- GPU内存
- 批次大小
- 上下文长度
- 每次请求的成本
- Infrastructure utilization
This distinction is important because using premium training hardware for every inference workload can significantly increase operating costs without necessarily producing proportional benefits.
NVIDIA H100: Best for High-End LLM Training
NVIDIA H100 is one of the best-known data center GPUs for large-scale artificial intelligence.
Built around NVIDIA's Hopper architecture, H100 is designed for demanding AI training, inference, generative AI, and high-performance computing workloads.
H100 servers are particularly relevant for:
- 大型语言模型的训练
- 生成式人工智能
- Transformer 工作负载
- LLM微调
- 企业级人工智能
- Multi-GPU AI infrastructure
The main disadvantage is cost. Smaller models and lower-utilization projects may achieve better value with less expensive accelerators.
For a detailed look at H100 infrastructure, see our
NVIDIA H100 服务器托管
指南。.
AMD Instinct MI300X: Best for High-Memory LLM Workloads
AMD Instinct MI300X has become an important alternative for organizations building large-model AI infrastructure.
Its major advantage is memory capacity. MI300X provides 192GB of HBM3 memory per accelerator, making it particularly interesting for models where GPU memory is a major constraint.
潜在的应用包括:
- 大型语言模型
- 生成式人工智能
- 大型模型推理
- 机器学习
- 内存密集型人工智能
- 高性能计算
The main consideration is software. AMD uses the ROCm ecosystem, so organizations migrating from NVIDIA infrastructure should verify model, framework, library, and application compatibility.
更多详情请参阅我们的
AMD Instinct MI300X 服务器
指南。.
NVIDIA A100: A Proven Option for AI Training
NVIDIA A100 predates H100 but remains relevant for many machine-learning and AI environments.
For organizations that do not require the performance characteristics of newer accelerators, A100 infrastructure may still provide useful performance for:
- 模型训练
- 微调
- 深度学习
- 人工智能研究
- 推论
- 数据科学
An older GPU generation should not automatically be rejected. What matters is whether its performance and current infrastructure cost fit the workload.
NVIDIA L40S: Strong Option for AI Inference
NVIDIA L40S is especially interesting when AI inference is combined with graphics-oriented workloads.
It can be considered for:
- Generative AI inference
- 图像生成
- 人工智能应用
- 计算机视觉
- 渲染
- 可视化
For workloads that do not require premium H100-class training infrastructure, L40S can provide a more balanced deployment option.
RTX GPU Servers: Affordable LLM Development
Not every LLM project starts at enterprise scale.
RTX-class GPUs can be useful for developers, startups, researchers, and smaller AI projects that need GPU acceleration without the cost of high-end data center hardware.
常见的使用场景包括:
- LLM开发
- 模型测试
- 小型模型推理
- Fine-tuning experiments
- 图像生成
- AI prototyping
The major limitation is usually GPU memory. Large models may require quantization, model partitioning, multiple GPUs, or higher-memory accelerators.
H100 vs A100 vs L40S vs MI300X for LLMs
| GPU | Training | 推论 | 主要优势 |
|---|---|---|---|
| NVIDIA H100 | Excellent fit | Excellent fit | High-end AI performance |
| AMD MI300X | 紧身 | 紧身 | 大容量 GPU 内存 |
| NVIDIA A100 | 紧身 | 紧身 | Mature platform |
| NVIDIA L40S | 取决于工作量 | 紧身 | 人工智能 + 图形 |
| RTX 显卡 | Smaller workloads | Smaller workloads | 成本更低 |
There is no universal winner because model size, precision, batch size, context length, framework optimization, and GPU utilization can significantly change real-world results.
For a closer NVIDIA comparison, see
H100 与 A100 与 L40S 对比.
How Much GPU Memory Does an LLM Need?
VRAM is one of the most important factors when selecting an LLM server.
内存需求取决于:
- Number of model parameters
- 数值精度
- 训练还是推理
- 上下文长度
- 批次大小
- KV cache
- 优化技术
A model that does not fit efficiently into GPU memory may require multiple accelerators or memory-saving techniques.
This is why selecting a GPU solely by compute specifications can be misleading. For many LLM workloads, available GPU memory can be just as important as raw processing power.
Multi-GPU Servers for LLM Training
Very large models often require multiple GPUs.
In these environments, the server must efficiently move data between accelerators. Multi-GPU performance therefore depends on much more than multiplying the performance of one GPU by the number of installed GPUs.
需要重点考虑的因素包括:
- GPU互连
- Memory architecture
- CPU平台
- 系统内存
- 存储吞吐量
- 网络架构
- Training framework
For distributed training across multiple servers, network performance becomes even more important.
CUDA vs ROCm for LLM Infrastructure
Software ecosystem is a major factor in the NVIDIA versus AMD decision.
NVIDIA CUDA
CUDA has a mature ecosystem and extensive adoption across artificial intelligence, machine learning, and GPU computing.
AMD ROCm
ROCm provides AMD's GPU computing software platform and continues to expand its support for AI and HPC workloads.
Before choosing between the two, verify:
- Framework support
- 模型兼容性
- 必需的库
- 容器支持
- Operating system compatibility
- Existing CUDA dependencies
- ROCm 优化
我们的
AMD GPU 服务器与 NVIDIA GPU 服务器对比
comparison explores this decision in more detail.
Best GPU Server Providers for LLMs
The provider determines more than the GPU itself. Storage, networking, billing flexibility, regions, server architecture, and deployment model can all affect the final result.
GPU Mart
GPU Mart focuses on GPU hosting and can be relevant to users looking for persistent GPU infrastructure and dedicated-style server deployments.
Before ordering, compare the exact GPU, CPU, RAM, NVMe storage, network configuration, traffic allowance, and contract terms.
数据库集市
数据库集市 combines traditional server infrastructure with GPU computing options, making it relevant to organizations that prefer server-oriented deployments rather than purely ephemeral cloud resources.
RunPod
RunPod is designed around flexible GPU computing for AI developers. Its cloud-oriented model can be useful for model development, training, fine-tuning, and inference workloads where demand changes over time.
Vast.ai
Vast.ai provides a GPU marketplace model where users can compare resources from different hosts.
This can be useful for cost-sensitive AI workloads, although buyers should compare host characteristics, reliability, storage, networking, and complete instance specifications rather than GPU price alone.
DigitalOcean
DigitalOcean combines GPU resources with a broader developer cloud environment. This can appeal to teams building AI applications that also need compute, storage, networking, databases, and related cloud infrastructure.
Dedicated GPU Server vs GPU Cloud for LLMs
| 因子 | 专用GPU服务器 | GPU 云 |
|---|---|---|
| 资源 | 专属 | 取决于平台 |
| 部署 | 取决于提供商 | 快 |
| 缩放 | 受硬件限制 | 灵活的 |
| 账单 | 通常每月一次 | 通常基于使用情况 |
| 最适合 | 稳定的利用率 | 可变的工作量 |
Dedicated GPU servers can make sense for continuously running LLM workloads where utilization is predictable.
GPU cloud infrastructure can be more attractive for development, temporary training jobs, experimentation, and workloads that need rapid scaling.
LLM Training: Dedicated or Cloud?
Consider a dedicated server when GPU utilization is consistently high and the workload needs predictable hardware access.
Consider GPU cloud when:
- Training is temporary
- GPU requirements change frequently
- You are testing different accelerators
- 您需要快速部署
- You want to avoid long-term hardware commitments
For a full deployment comparison, read
NVIDIA GPU 服务器与 GPU 云的对比.
How Much Does an LLM GPU Server Cost?
There is no single LLM server price because infrastructure requirements vary dramatically.
Total cost can include:
- GPU计算
- GPU 数量
- CPU 资源
- 系统内存
- NVMe 存储
- 网络带宽
- 数据传输
- 持久化存储
- Idle capacity
- 管理与支持
Hourly GPU pricing alone does not tell you which server provides the best value.
A more expensive GPU may complete a workload faster, while a cheaper accelerator may provide better economics for continuous inference.
请参阅我们的
AI 服务器成本指南
for a broader breakdown of AI infrastructure costs.
Best GPU Server by LLM Workload
| 工作量 | GPU 评估方向 |
|---|---|
| 大型语言模型(LLM)训练 | H100 / high-end AMD Instinct |
| 大型模型推理 | H100 / MI300X / suitable alternatives |
| Fine-Tuning | H100 / A100 / workload-specific GPU |
| AI推理 | L40S / H100 / MI300X / RTX depending on model |
| LLM Development | RTX / 经济实惠的云端 GPU |
| 人工智能研究 | A100 / H100 / suitable GPU cloud |
Common LLM GPU Server Mistakes
选择最昂贵的显卡
A premium accelerator does not guarantee the best price-performance ratio for every model.
忽略显存
GPU memory can determine whether the model runs efficiently at all.
Using Training Hardware for Every Inference Workload
Inference may have very different performance and cost requirements from training.
忽视软件兼容性
CUDA and ROCm compatibility can significantly affect deployment complexity.
Comparing Only Hourly GPU Prices
The real metric is total workload cost, not simply the advertised price of one GPU hour.
LLM GPU Server Selection Checklist
- Identify whether the workload is training or inference.
- Determine the model size.
- 计算 GPU 内存需求。.
- Choose the required software ecosystem.
- Determine whether multiple GPUs are necessary.
- 估算预期的 GPU 利用率。.
- Compare dedicated and cloud infrastructure.
- Check storage and networking.
- 计算总工作量成本。.
- 为未来的扩展做好规划。.
结语
The best GPU servers for LLM training and AI inference depend on what the model actually needs.
NVIDIA H100 is designed for demanding AI and large-scale training. AMD Instinct MI300X offers substantial GPU memory for memory-intensive LLM workloads. A100 remains useful for established AI environments, while L40S and RTX-class GPUs can provide better economics for inference, development, and smaller workloads.
The deployment model matters as well. Dedicated GPU servers can provide predictable resources for continuous workloads, while GPU cloud platforms make it easier to experiment, scale, and pay for infrastructure only when needed.
Do not begin with the question, “Which GPU is the most powerful?” Begin with the model and workload.
更好的决策路径是:
LLM → Training or Inference → VRAM → Software → GPU → Infrastructure → Cost.