Renting a powerful GPU for AI experiments can be expensive, especially when model training requires many hours of uninterrupted computation. Interruptible GPU rentals promise lower prices, but the savings come with an important tradeoff: your workload may stop before it finishes.
Vast.ai spot GPU rentals offer access to marketplace hardware through a bidding system. Developers can experiment with machine learning models, run batch inference, and fine-tune neural networks without purchasing physical accelerators.
However, the lowest advertised GPU rate is not necessarily the cheapest way to complete an experiment. Interrupted jobs, missing checkpoints, repeated setup, and ongoing storage charges can change the economics substantially.
This review explains how Vast.ai interruptible instances work, how to protect training progress, and when alternative GPU hosting options may deliver better value.
Editorial note: GXCOM.NET evaluates published platform documentation and practical infrastructure considerations. We have not independently benchmarked Vast.ai interruption frequency, host reliability, or GPU performance.
How Vast.ai Spot GPU Rentals Work
Vast.ai operates a marketplace where independent infrastructure hosts offer GPU capacity. Available listings can differ in GPU model, VRAM, CPU resources, storage, networking, location, and reliability.
Its interruptible rental model uses bids rather than a universally fixed spot price. Customers specify what they are willing to pay, and competing demand influences which instance receives priority.
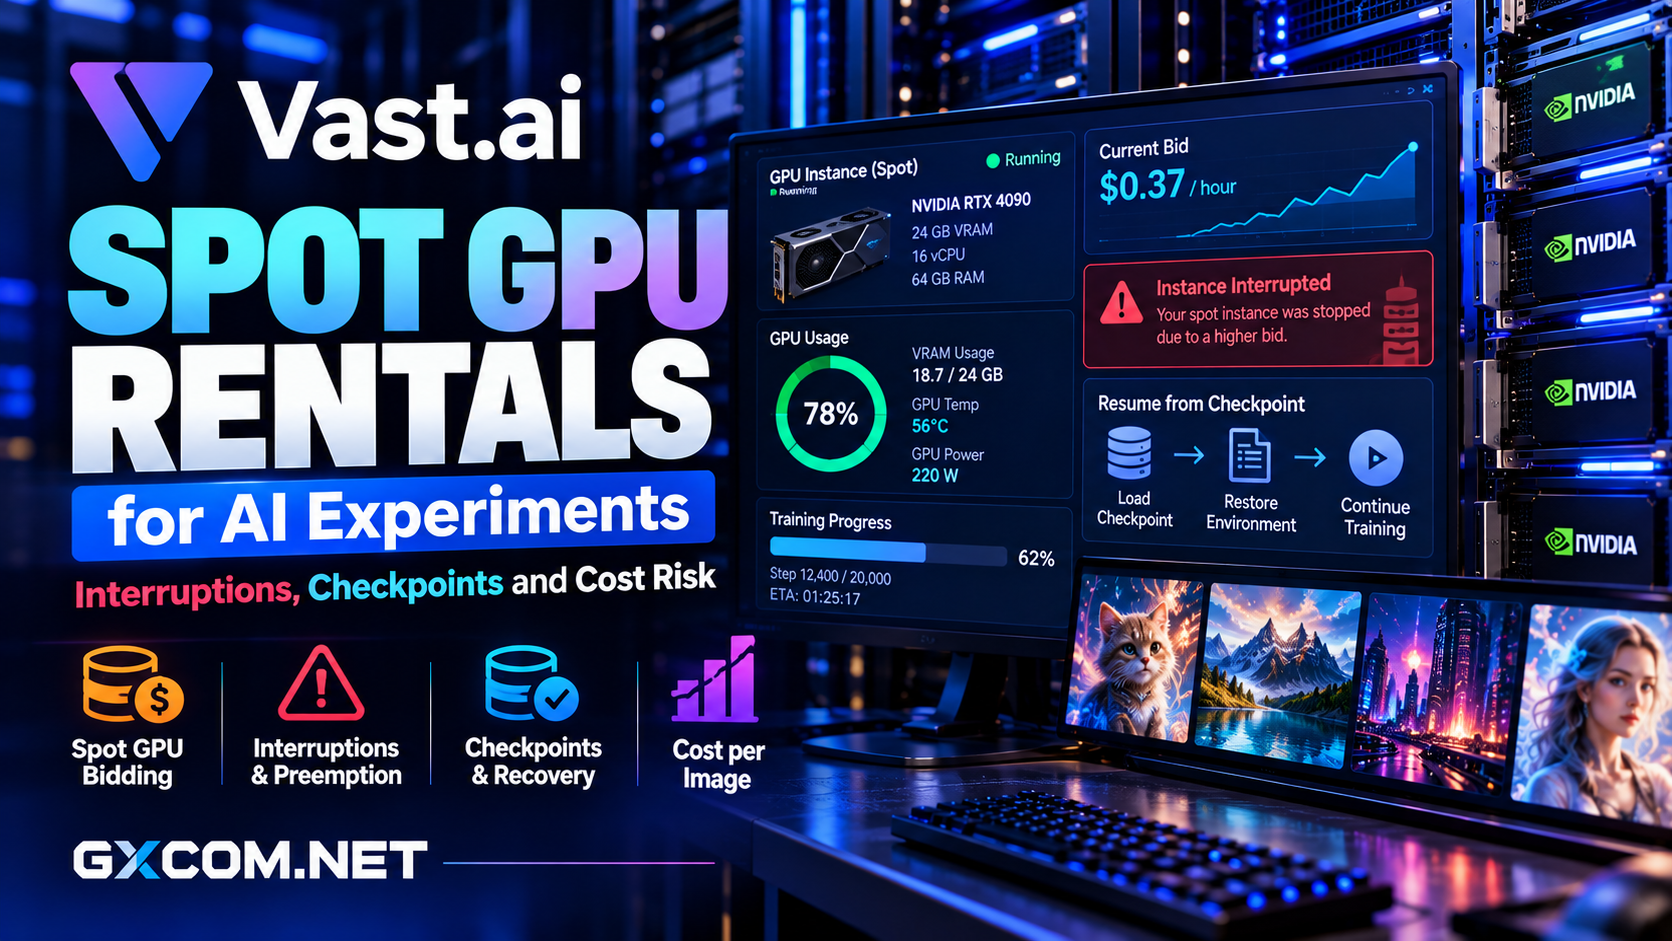
When another customer submits a higher bid or rents the resources on demand, an interruptible instance can be paused. Running processes stop, and the workload must be restarted or resumed later.
Unlike a scheduled maintenance window, interruption timing is uncertain. This makes spot rentals best suited to jobs that tolerate pauses and can recover without substantial manual intervention.
Spot Versus On-Demand GPU Instances
Vast.ai also offers on-demand rentals with higher priority. These are generally more suitable when predictable execution matters, although infrastructure failures and other operational risks can still occur.
Interruptible instances may offer meaningful discounts, but savings depend on marketplace conditions and successful job completion.
For example, a short image classification experiment may recover easily after interruption. A long training run that never saves intermediate progress could lose hours of computation.
Before bidding, compare GPU specifications, host reliability indicators, storage charges, network costs, and the remaining rental duration.
我们的 经济实惠的GPU服务器指南 covers additional rental and purchasing considerations.
What Happens When a GPU Instance Is Interrupted?
When an interruptible Vast.ai instance loses priority, active processes are stopped. Data previously written to the instance disk may remain available while the instance exists, but work held only in memory is lost.
There is no guarantee that the same GPU capacity will become available immediately. Waiting for the original instance to resume may delay experiments significantly.
Developers should therefore separate three kinds of data:
- Reproducible files: container images, scripts, and downloadable model weights.
- Recoverable training state: checkpoints, optimizer state, and scheduler information.
- Irreplaceable outputs: completed models, experimental results, and valuable datasets.
Store critical outputs outside the rented machine whenever practical. Local persistence alone is not sufficient protection against host problems, deletion, or contract expiration.

Checkpointing: The Key to Reliable Spot Training
Checkpointing saves training progress so an interrupted workload can resume without starting from the beginning.
For PyTorch and similar frameworks, a useful checkpoint may include model weights, optimizer state, learning-rate scheduler state, global training step, and relevant random-number generator states.
Saving only model weights may be adequate for inference or some adapter workflows, but it may not reproduce the original training trajectory accurately.
选择检查点间隔
Frequent checkpoints reduce potential lost computation but consume storage and I/O resources. Infrequent checkpoints improve uninterrupted throughput while increasing recovery risk.
A practical starting point is to estimate how much work the team can afford to repeat, then choose an interval that keeps expected losses manageable.
For longer training runs, measure checkpoint writing time and adjust frequency based on observed interruption patterns rather than assuming one interval works universally.
External Storage and Recovery Testing
Upload important checkpoints to independent object storage or another reliable destination. Use versioned filenames or atomic save procedures to avoid treating incomplete files as valid recovery points.
Test restoration before launching an expensive experiment. A checkpoint is useful only if the model, dependencies, configuration, and required data can be reconstructed successfully.
For related GPU memory planning, see our NVIDIA GPU服务器供应商对比.
Automating Recovery After Interruptions
Manual restarts can eliminate much of the financial advantage of low-cost compute. A better workflow uses repeatable container environments, startup scripts, and automated checkpoint discovery.
Vast.ai documents startup commands that can execute when an instance starts. Developers can use this mechanism to reinstall required dependencies, locate the latest valid checkpoint, and resume the training script.
Recovery automation should also verify available GPU memory, storage mounts, dataset integrity, and framework compatibility before restarting.
Log every interruption and restart. These records help reveal whether a low bid is creating excessive delays or repeated failures.
Calculating the Real Cost of Spot GPU Rentals
The most important metric is cost per successful experiment, not the displayed hourly GPU rate.
一个实用的公式是:
Total Cost = Billable GPU Runtime + Storage + Data Transfer + Recovery Overhead
Suppose a hypothetical interruptible GPU costs $0.40 per hour. A training job requiring ten productive hours would have a $4 compute cost without interruptions.
If interruptions and recovery increase billable runtime to fifteen hours, compute rises to $6. Additional storage and transfer charges increase the total further.
These figures are illustrative, not current Vast.ai pricing or measured interruption statistics.
Storage Costs Continue During Pauses
Vast.ai documents separate charges for GPU compute, storage, and bandwidth. Storage charges can continue while an instance is stopped, so waiting indefinitely for a low-priority instance to resume may still generate expenses.
Delete resources that are no longer needed, but export important data first. Review the current listing and billing rules because marketplace hosts can have different prices.
Time Has an Economic Cost
A delayed experiment can postpone product testing, model evaluation, or a customer delivery. Even if the GPU bill is lower, the business outcome may be worse.
Teams should set a maximum acceptable completion time and switch to higher-priority capacity when the delay exceeds that limit.
Choosing the Right GPU and Marketplace Host
GPU selection should begin with the workload rather than the cheapest listing.
Check VRAM capacity, GPU generation, CUDA compatibility, available system RAM, CPU resources, disk performance, and network transfer requirements.
Host reliability indicators provide useful context, but they cannot guarantee that an interruptible rental will remain available.
For sensitive datasets, examine the marketplace hosting model carefully. Avoid placing confidential information on infrastructure without appropriate security controls, contractual protections, and verified data-handling arrangements.
Vast.ai Alternatives for AI Experiments
RunPod: Container-Based GPU Workflows
RunPod offers GPU Pods for machine learning experiments and model fine-tuning. Its container-oriented environment and network volume options can simplify workflows requiring reusable datasets and checkpoints.
However, stopping a Pod may release its GPU allocation. Developers should understand the relevant storage and restart behavior before deployment.
GPU Mart: Dedicated GPU Capacity
GPU Mart is worth evaluating when experiments evolve into sustained workloads that benefit from dedicated GPU resources.
Compare hardware specifications, storage, operating-system support, and rental commitments against actual GPU utilization.
Cherry Servers: Bare Metal for Predictable Workloads
Cherry 服务器 provides dedicated infrastructure for teams requiring greater hardware control and predictable capacity.

Its bare metal approach may be appropriate for long-running training or inference, although management responsibilities and fixed infrastructure costs require consideration.
探索我们的 AI GPU VPS 服务商指南 以及 裸机服务器提供商对比 for broader alternatives.
Who Should Use Vast.ai Interruptible GPUs?
Vast.ai interruptible rentals are best suited to researchers, developers, and experimental teams running fault-tolerant workloads with flexible deadlines.
Good candidates include checkpointed model fine-tuning, batch processing, reproducible benchmarks, and nonurgent experiments.
They are less suitable for real-time customer applications, deadline-critical training, or jobs that cannot reliably resume.
最终裁决
Vast.ai spot GPU rentals can reduce AI experimentation costs when workloads are designed for interruption and recovery.
The platform’s marketplace model offers flexibility, but buyers must account for bidding competition, host differences, persistent storage charges, and the possibility of delayed completion.
Choose interruptible capacity for recoverable experiments. Consider RunPod for alternative GPU workflows, or compare GPU Mart and Cherry Servers when continuous dedicated capacity becomes more important than the lowest possible rental rate.
常见问题解答
Can Vast.ai spot instances stop unexpectedly?
Yes. Higher bids or competing on-demand rentals can interrupt an instance, stopping its running processes.
Do interrupted Vast.ai instances lose all files?
Not necessarily. Files written to persistent instance storage may remain while the instance exists, but memory-only progress is lost. External backups remain important.
Does Vast.ai charge for stopped instances?
Storage charges can continue while an instance is stopped. Check the current billing rules and delete unused resources after exporting necessary data.
Are spot GPUs suitable for production AI services?
Generally, they are better suited to fault-tolerant background workloads. Production services requiring predictable availability should prioritize more reliable capacity arrangements.