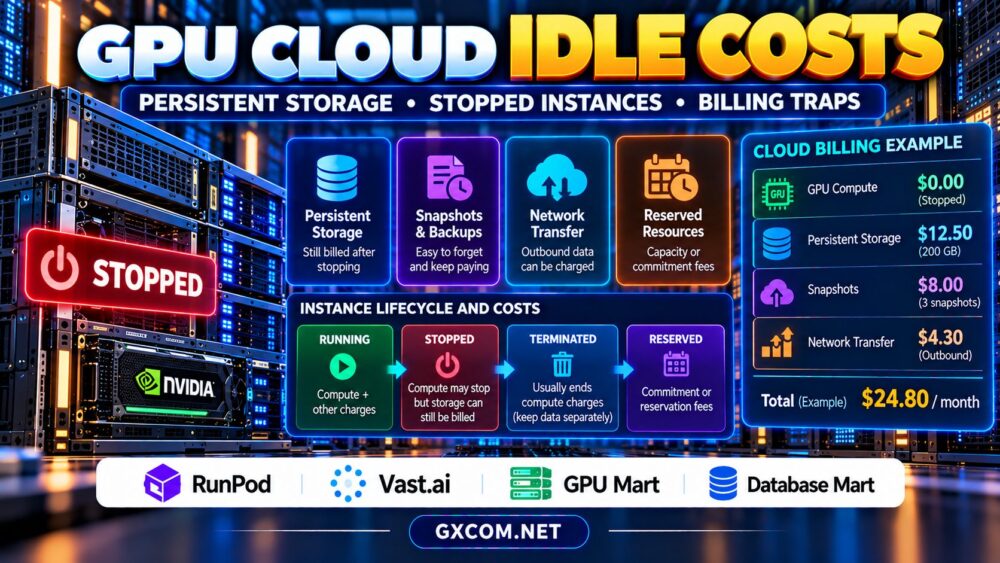
GPU cloud idle costs can turn an affordable hourly rental into an unexpectedly expensive AI hosting bill. Developers often assume that stopping a GPU instance stops every charge. In reality, persistent storage, reserved capacity, networking resources, and other services may continue generating costs after GPU computation ends.
Understanding these charges is essential when comparing cheap GPU servers for machine learning, image generation, model training, or inference. This guide explains the difference between stopping and deleting instances, identifies common billing traps, and shows how to calculate your actual GPU hosting expenses.
What Are GPU Cloud Idle Costs?
GPU cloud idle costs are expenses incurred when rented infrastructure is not performing useful work. They can arise while an instance remains powered on without processing jobs, or when associated resources continue billing after compute stops.
There are two important distinctions: an idle but running GPU may still incur full compute charges, while a stopped instance may retain separately billable resources.
Billing behavior varies by provider, product, and resource type. Never assume that a dashboard status labeled “Stopped” means your entire account has stopped accumulating charges.
Running vs Stopped vs Terminated GPU Instances
GPU hosting platforms use different lifecycle terminology. Understanding the practical meaning of each state helps prevent avoidable expenses.
| Instance State | Compute Billing | Other Possible Charges |
|---|---|---|
| Running | Usually active, even when GPU utilization is low | Storage, network, additional services |
| Stopped | May stop, depending on product | Persistent disks, reserved resources |
| Terminated or deleted | Usually ends instance compute billing | Retained volumes, snapshots, external services |
| 预留容量 | Depends on reservation agreement | Commitment or reservation charges |
These are general billing patterns, not universal guarantees. Some services do not support stopping instances while preserving their original GPU allocation.
Check whether restarting requires obtaining new capacity, whether local data survives, and which resources remain attached after termination.
Persistent Storage: The Most Overlooked Expense
AI workloads often require large model checkpoints, training datasets, container images, and generated outputs. Keeping these files available between sessions can reduce setup time, but persistent storage may be billed independently.
Suppose a hypothetical service charges $0.10 per GB-month for retained storage. Keeping 200 GB would cost approximately $20 per month, even if GPU computation were inactive. This is an illustrative calculation, not a current provider quote.
Separate persistent volumes from temporary instance storage. Temporary disks may disappear when an instance is deleted, while persistent volumes may remain until explicitly removed.
Before deleting anything, back up valuable data and verify that the backup can be restored. Removing the only copy of a trained model is rarely worth a small storage saving.

Five Common GPU Cloud Billing Traps
1. Leaving an Idle GPU Running
A GPU can show near-zero utilization while its instance continues billing. Forgotten notebooks, disconnected SSH sessions, and completed training jobs are common causes.
2. Keeping Unused Persistent Volumes
Volumes may survive instance deletion. Review unattached disks, old checkpoints, and duplicate datasets regularly.
3. Confusing Stopping With Releasing Capacity
Some hosting arrangements retain resources or commitments after workloads stop. Read the product-specific lifecycle and reservation policies.
4. Ignoring Network and Transfer Costs
Moving large datasets or model outputs can create additional expenses where outbound traffic is metered. Check transfer allowances and billing boundaries.
5. Forgetting Snapshots and Backups
Snapshots are useful for recovery, but multiple retained versions may increase storage usage. Establish a retention policy instead of accumulating backups indefinitely.
How Much Can an Idle GPU Cost?
Consider an illustrative GPU instance priced at $0.70 per active hour. If it runs continuously for a 30-day month, the compute bill reaches $504, regardless of whether useful jobs occupy every hour.
If actual workloads require only 100 hours, active compute would total $70 under a strictly usage-based arrangement. Adding a hypothetical $15 monthly storage charge brings the total to $85, assuming no additional fees.
The difference is substantial, but it depends on whether the service supports stopping or releasing compute without ongoing reservation charges.
For image generation workloads, combine these calculations with our 每张AI图像的GPU租赁费用指南 to evaluate both productive and idle spending.
RunPod, Vast.ai, GPU Mart, and Database Mart
RunPod: Evaluate Compute and Storage Separately
RunPod is relevant for GPU development and inference deployments. When comparing its available products, examine compute billing, storage persistence, deployment lifecycle, and what happens when a workload stops.
请查看我们的 RunPod GPU 云服务评测 以获取有关该服务提供商的更多背景信息。.
Vast.ai: Compare Individual Rental Offers
Vast.ai is useful for comparing GPU rental options, particularly when workloads are intermittent. Marketplace offers can differ in hardware, storage arrangements, and operational conditions.
Evaluate each listing’s actual billing and data-retention rules before assuming that the lowest hourly compute price delivers the lowest monthly cost.
GPU Mart: Assess Persistent Hosting Economics
GPU Mart is worth considering when you need a longer-lived GPU environment. Compare available configurations, payment periods, included storage, and whether the selected product offers flexible shutdown or fixed-term billing.
A predictable monthly plan can be appropriate for consistently busy workloads, but less attractive for occasional experimentation.
Database Mart: Supporting Infrastructure Costs
数据库集市 may be evaluated for related server and storage requirements. Confirm product-specific capabilities and billing terms; ordinary VPS or database hosting should not be mistaken for GPU compute.
Keeping datasets on separate infrastructure may simplify some workflows, although transfer latency and network costs must also be considered.
How to Reduce GPU Cloud Idle Costs
Start by monitoring GPU utilization, instance uptime, and actual job completion times. Configure shutdown automation where supported, and use alerts for unexpected spending.
Schedule batch training and image generation instead of leaving interactive environments running continuously. Store reusable datasets and checkpoints on appropriately priced persistent storage.
Delete unattached volumes only after confirming that their contents are no longer needed. Review snapshots, reserved capacity, and networking resources separately.
我们的 经济实惠的GPU服务器对比 helps identify broader purchasing considerations, while the GPU VPS versus dedicated GPU server guide explains deployment tradeoffs.
Hourly vs Monthly GPU Hosting: Which Is Cheaper?
Hourly GPU rental generally deserves consideration for irregular experiments, short training jobs, and occasional inference. Monthly hosting can make more sense when utilization is consistently high and the workload requires stable resources.

Calculate your break-even point by dividing the monthly plan cost by the effective hourly alternative, including relevant storage and ancillary charges.
For example, a hypothetical $180 monthly plan breaks even against $0.75 per compute hour at 240 active hours, before differences in included resources and fees.
比较 AI inference server sizing requirements before committing to continuously running capacity.
Compare GPU Hosting Beyond the Hourly Price
Check storage charges, shutdown policies, billing periods, and total workload costs before choosing your next GPU hosting provider.
常见问题解答
Do stopped GPU instances still cost money?
They can. Persistent storage, reserved capacity, snapshots, and other retained resources may continue billing depending on the provider and product.
Does deleting a GPU instance remove its storage?
Not always. Some persistent volumes and backups remain independently billable until explicitly deleted.
How can I avoid paying for an unused GPU?
Monitor utilization, automate supported shutdown procedures, review retained resources, and configure billing alerts before launching expensive workloads.
最终裁决
Cheap GPU hosting requires more than a low hourly rate. Understand instance states, persistent storage, reservation commitments, and transfer charges before purchasing. Compare RunPod, Vast.ai, GPU Mart, and relevant 数据库集市 infrastructure against your actual usage pattern, then monitor costs throughout deployment.